Earlier this year, I opened Linear to discover that Tuomas, our CTO, had assigned an matter to me, titled “CI expenses are high.” While I was at it, he additionally wanted me to create CI faster.
Agents have made it exponentially faster to container code, but validating those changes hasn’t fairly kept up at the identical rate. Every PR motionless has to continue through CI, so as betterment accelerates, CI becomes a bottleneck, driving up infrastructure expenses and leaving developers and agents waiting longer for feedback.
In our chase to create CI additional performant at Linear, we optimized for how lengthy a PR waits on CI and how much runner period it consumes. Despite our test suites nearly quadrupling since the commencement of the year, we brought drag petition delay period downward from additional than 6 minutes to fair complete 5, during cutting runner period per test approximately in half.
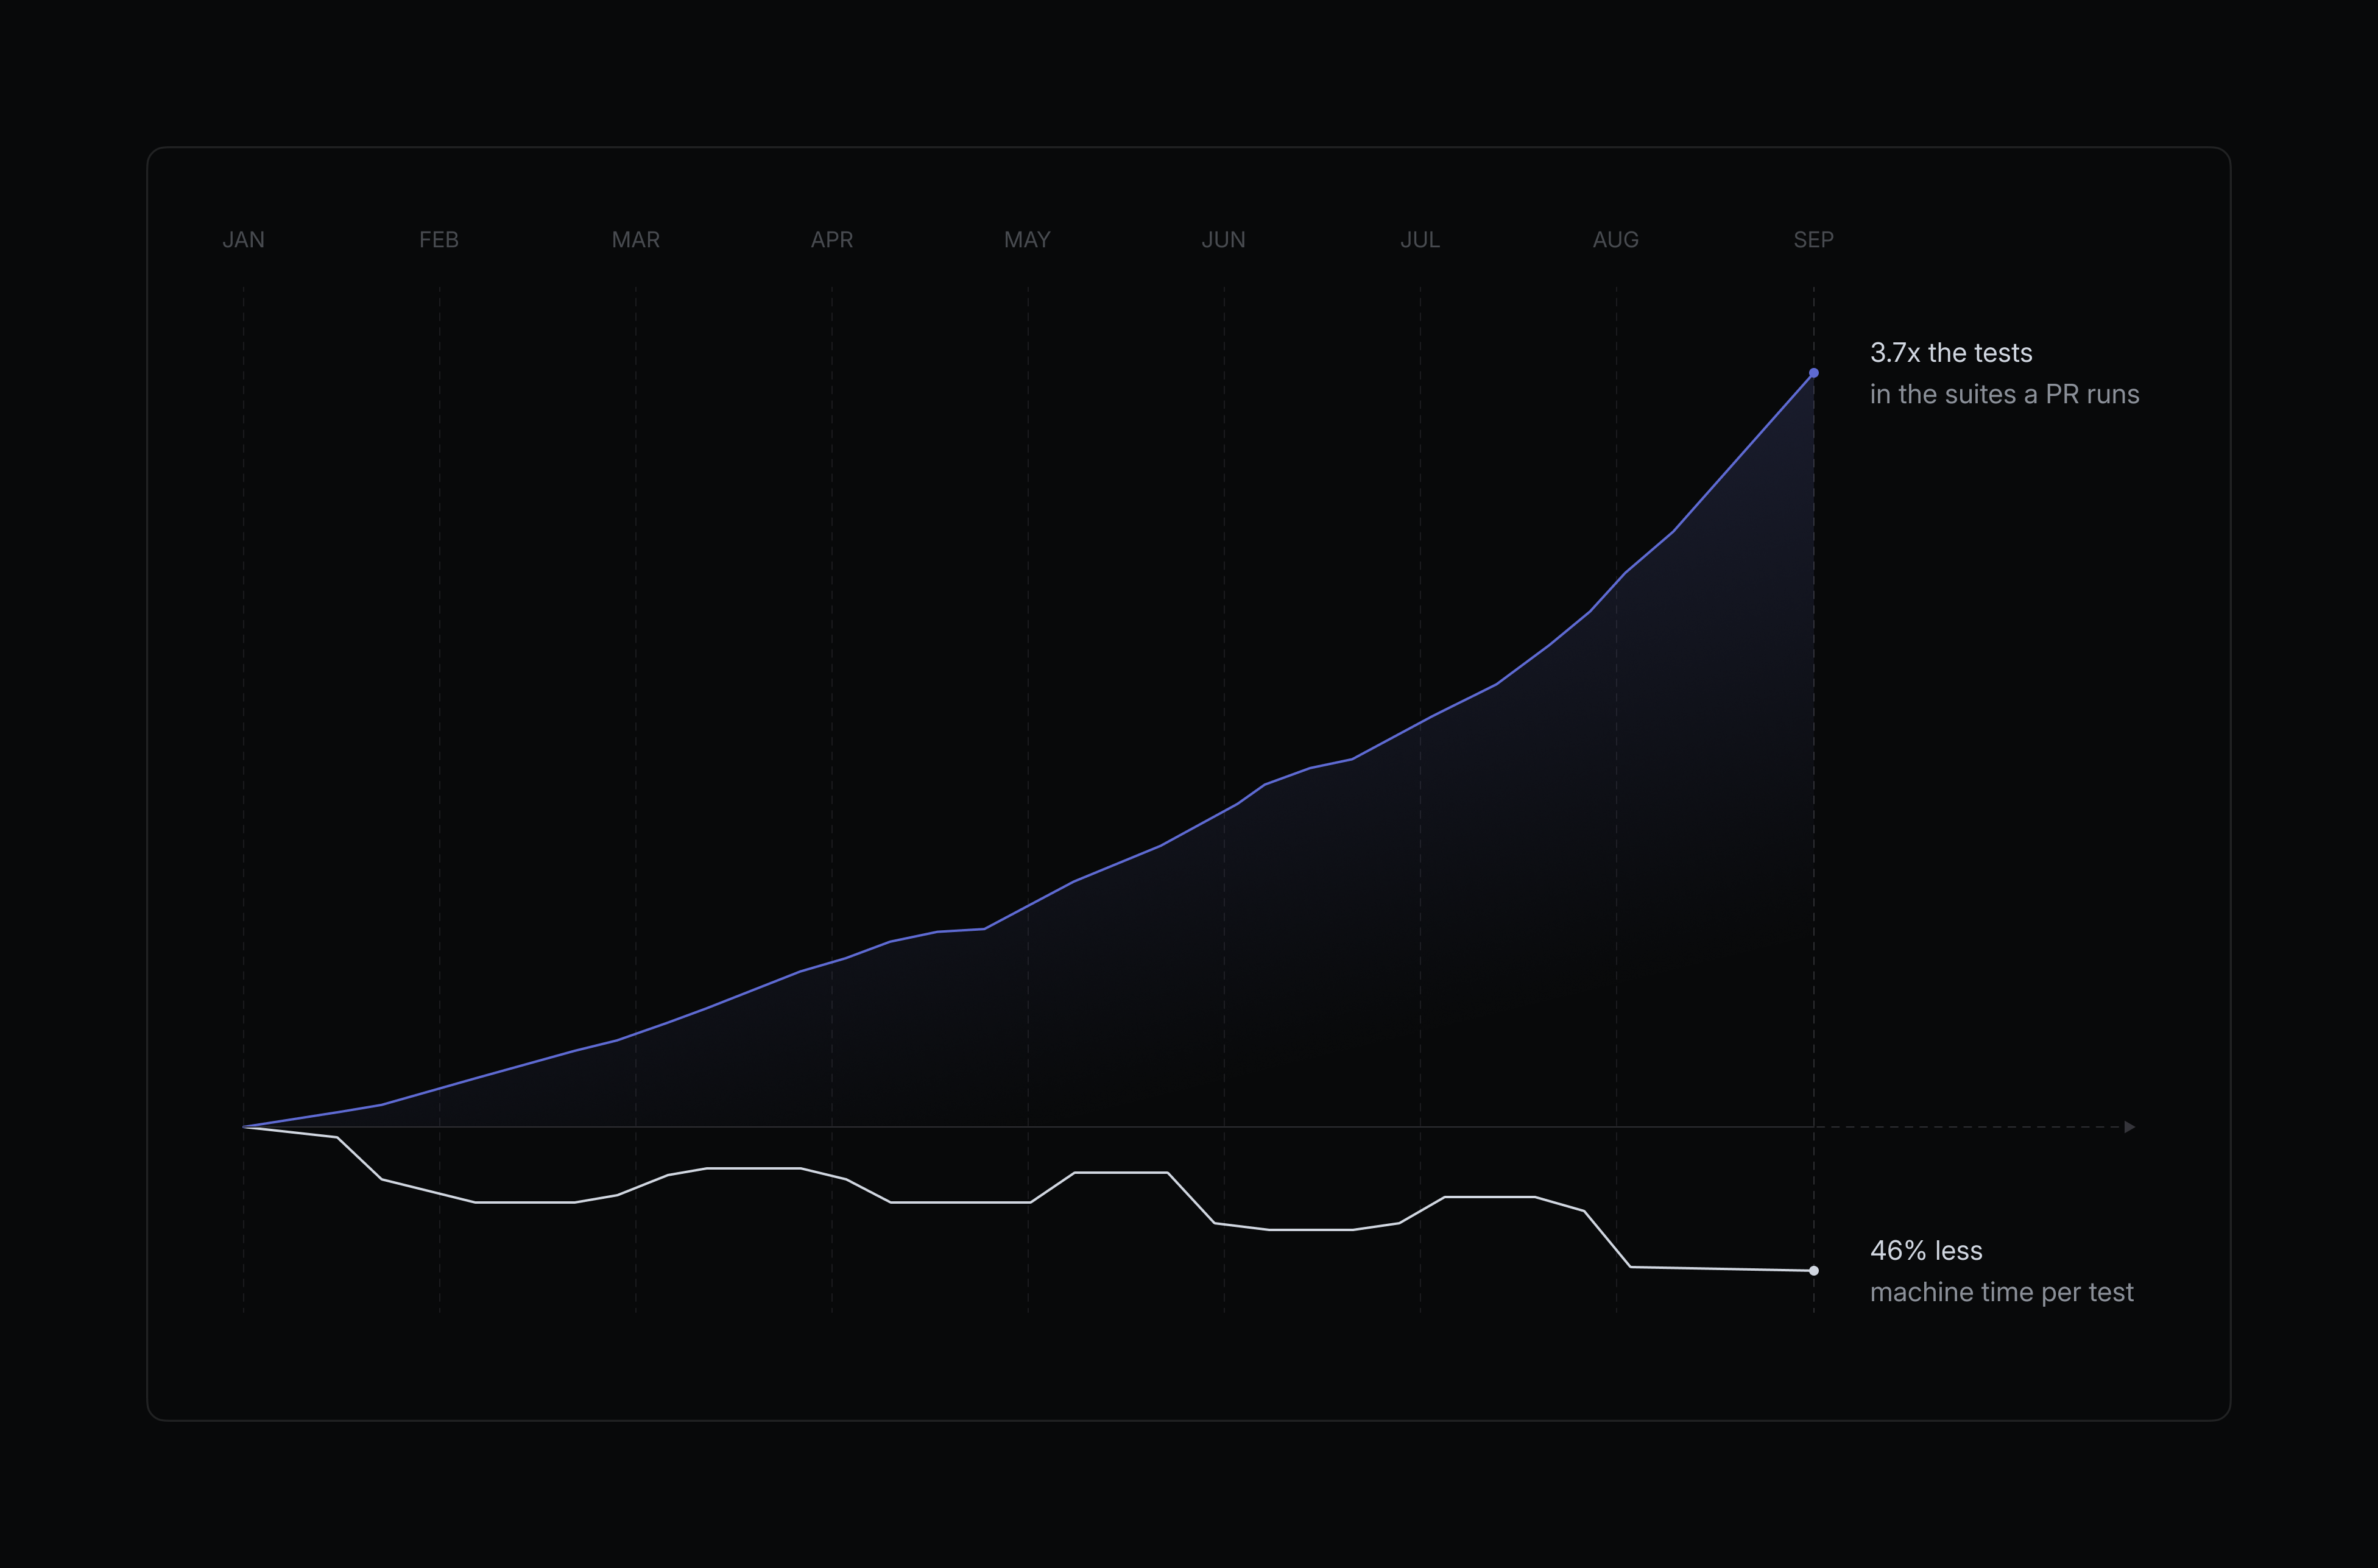
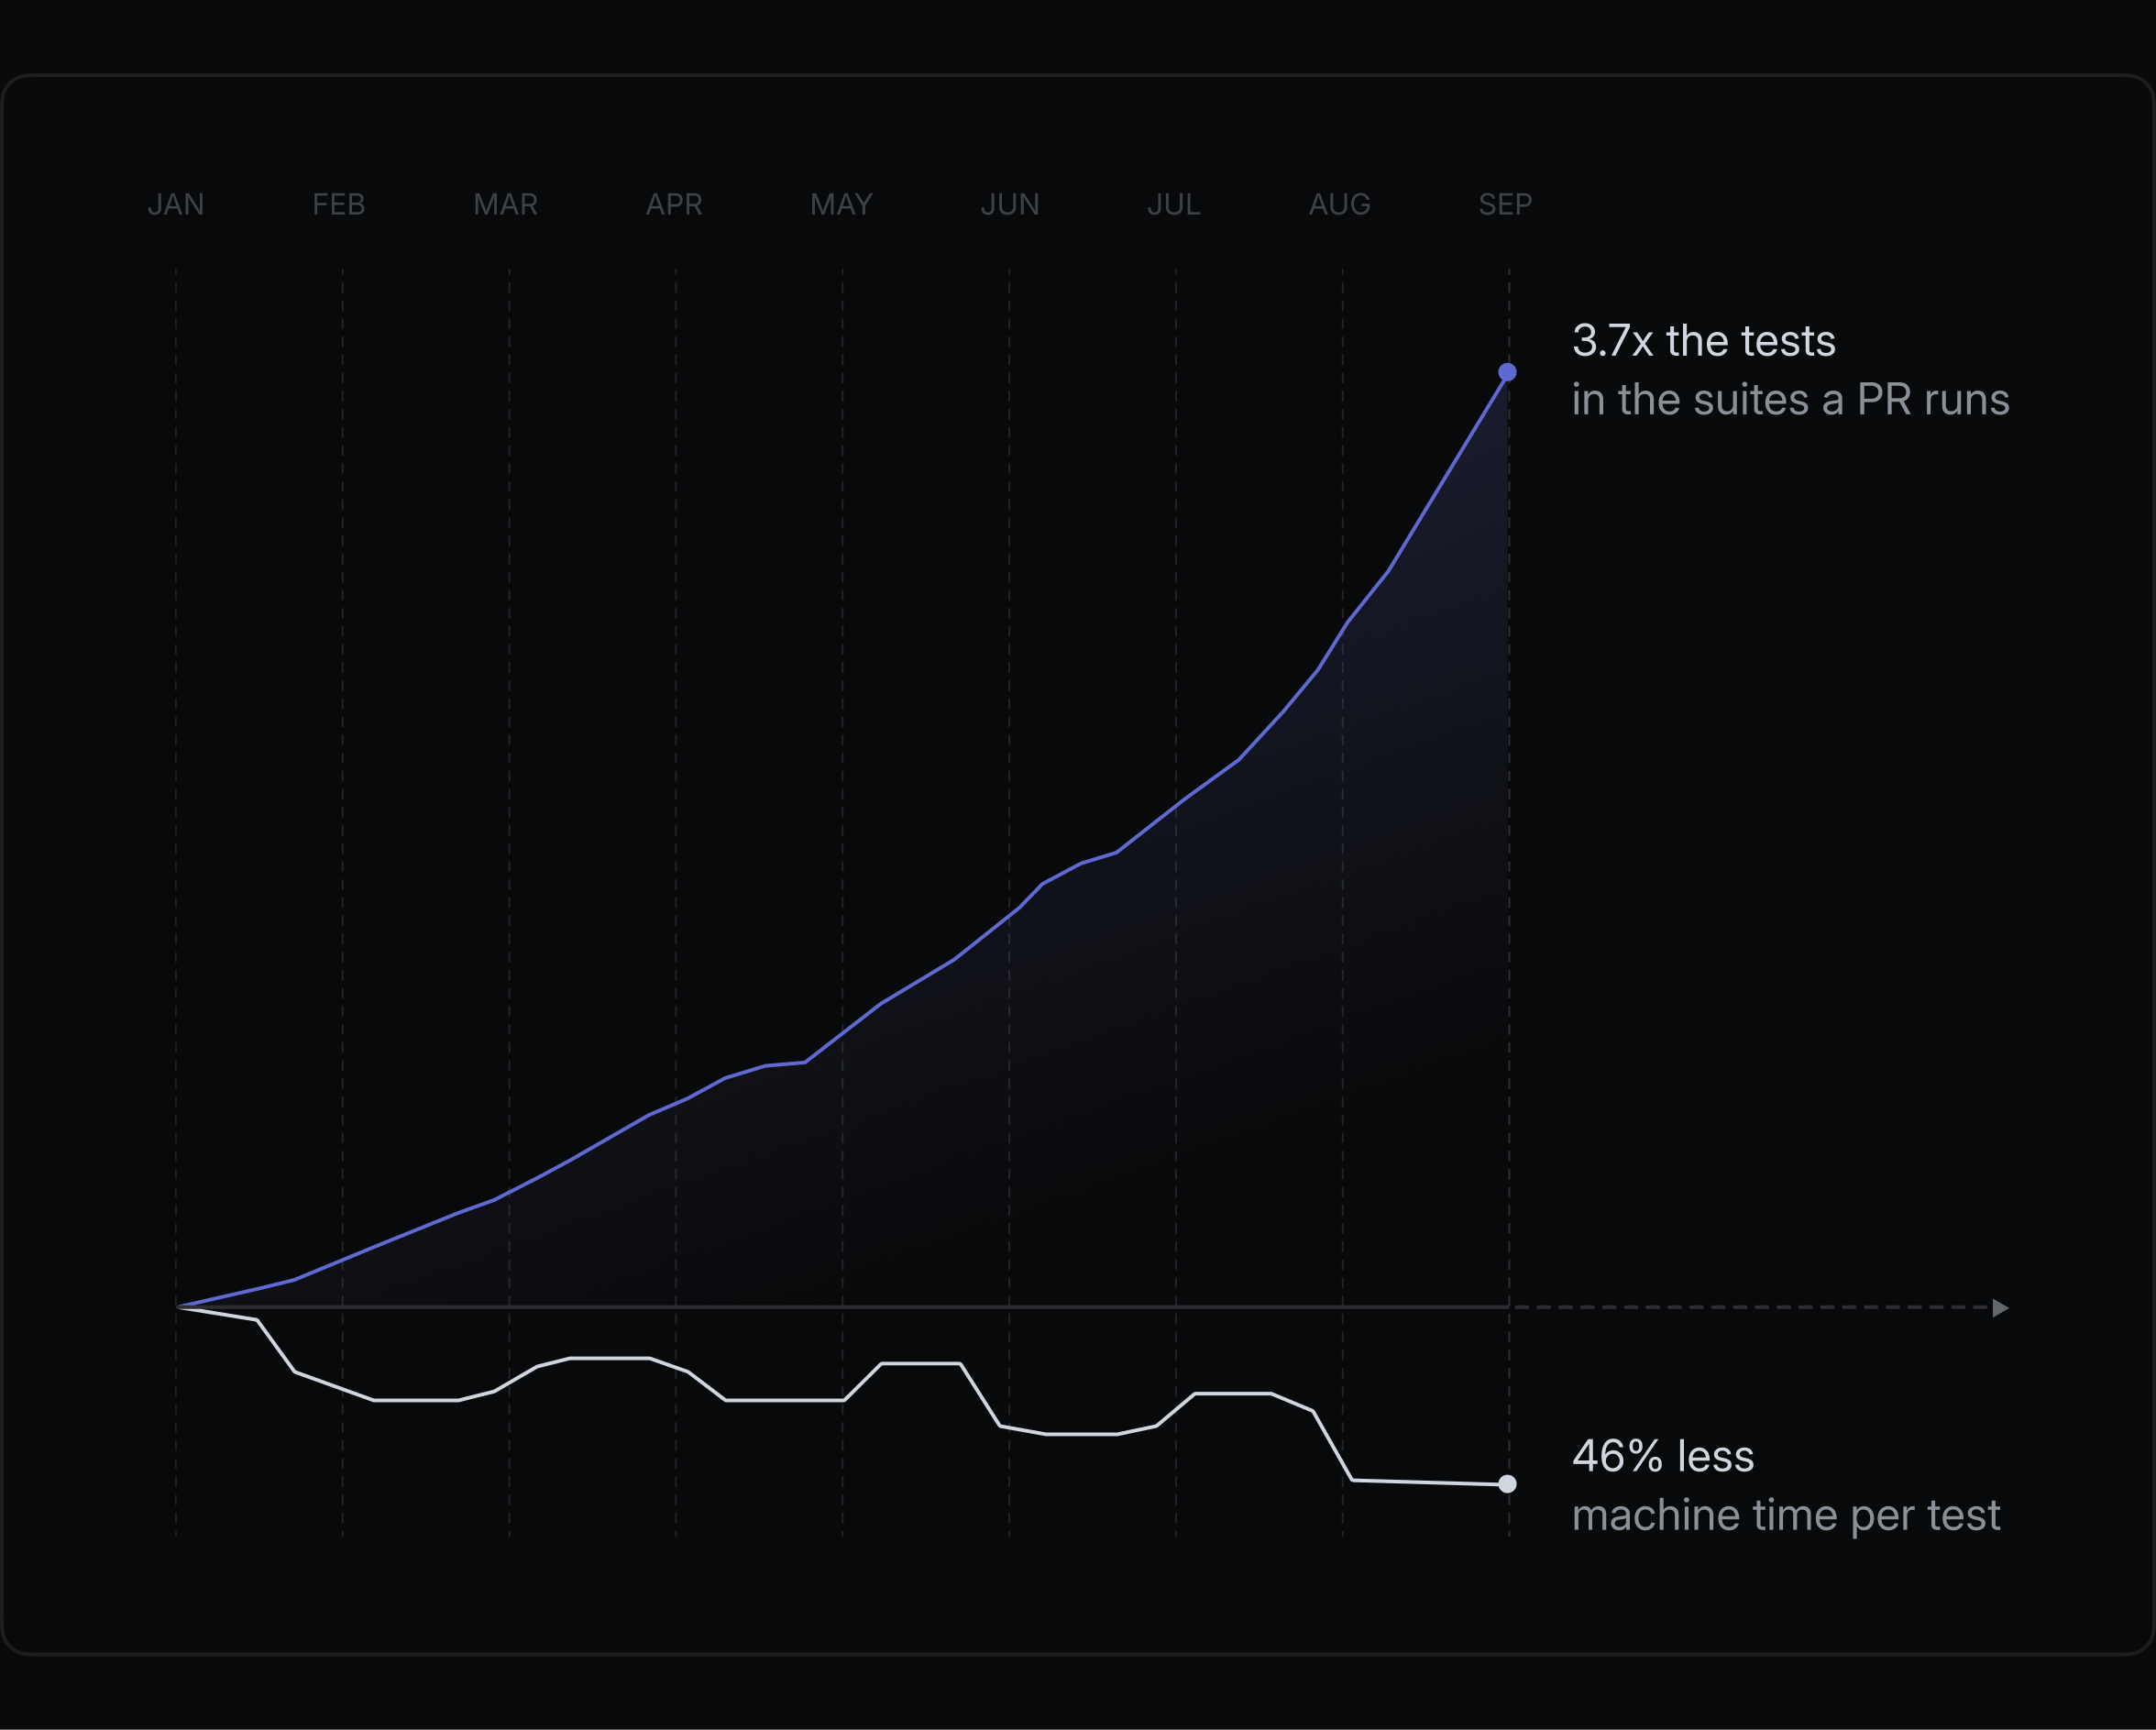
This is test suite achievement indexed to the archetypal week of January. The pale line, tracking device period per test, spikes whenever we added test shards, which shorten the delay and expenses additional device time, and again during checkout stalling issues
Broadly, we improved CI in four ways:
- Upgraded infrastructure and tooling
- Optimized the jobs that entrance another work
- Reduced repeated setup
- Made test implementation additional efficient
Linear’s codebase is chiefly TypeScript, but many of these optimizations use throughout languages and toolchains.
Upgraded infrastructure and tooling
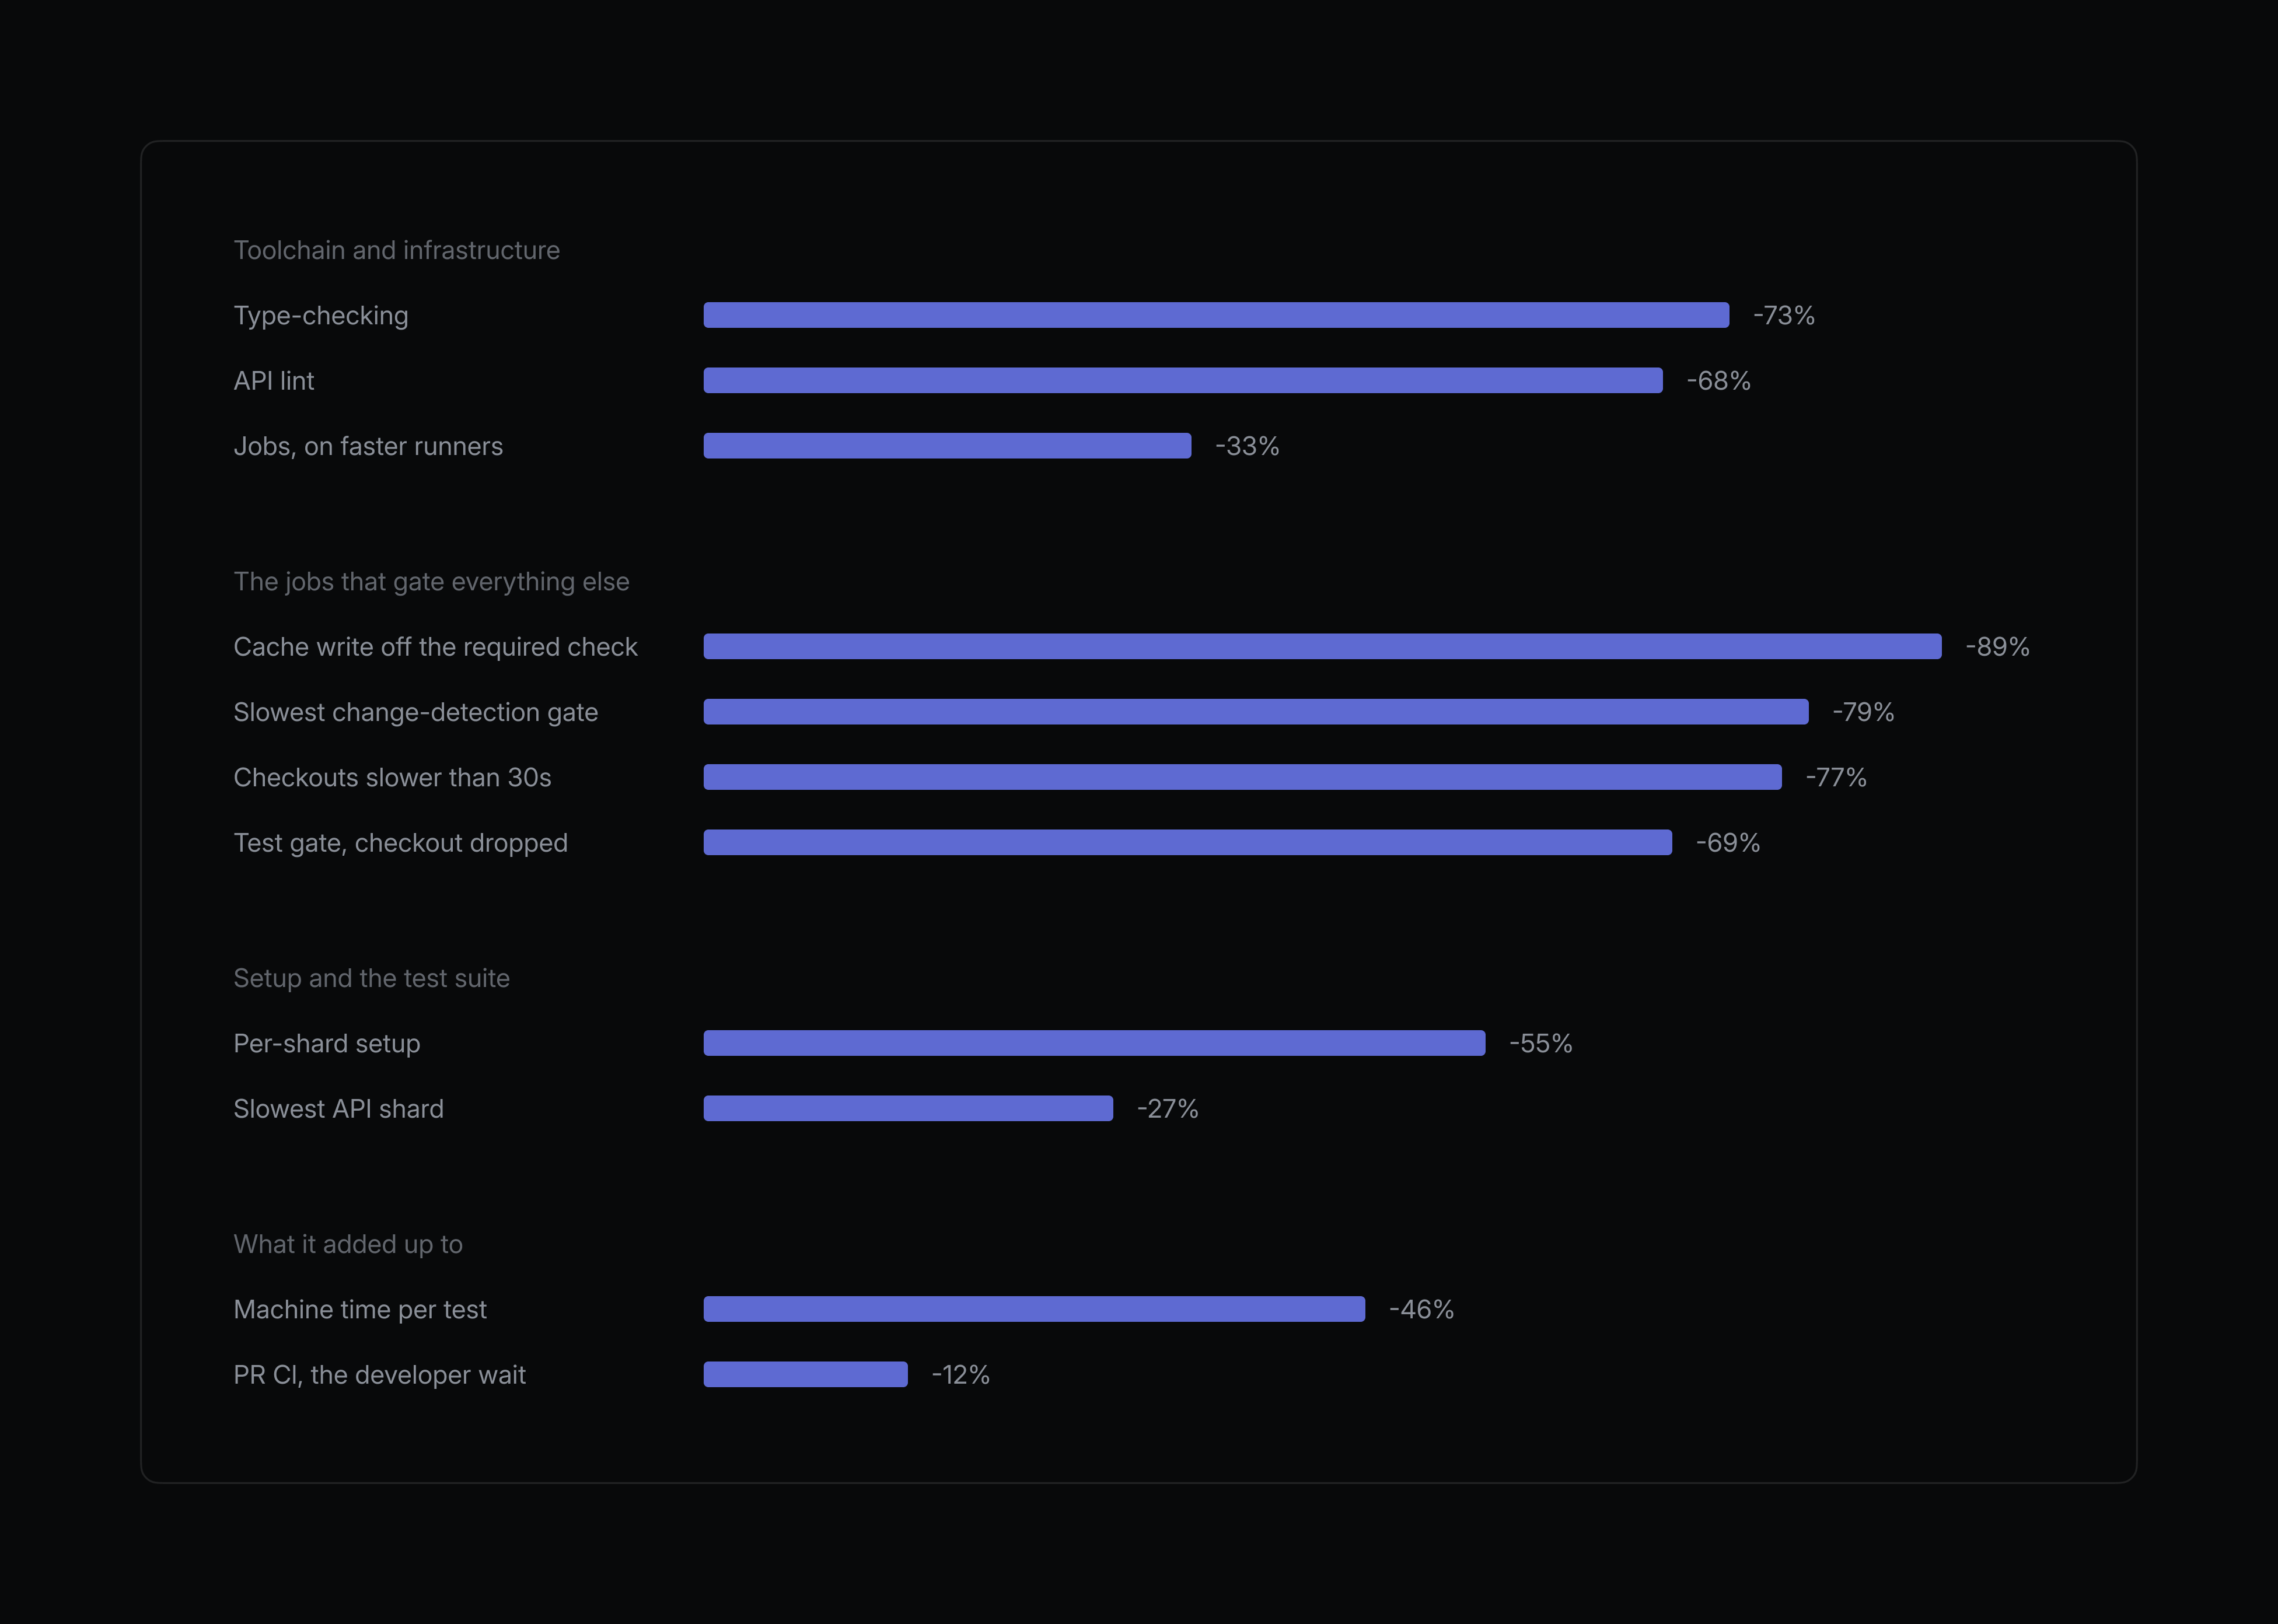
Some of our earliest gains required nearly no optimization of CI itself. Moving our workloads off GitHub Actions to third-party runners alongside faster CPUs, higher-performance storage, and improved cache infrastructure gave us faster machines to run the identical pipeline on. In a like-for-like difference of the two days either flank of the switch, jobs ran 34% faster on average, alongside several workloads akin tsc dropping 52%.
Separately, modernizing our toolchain additionally paid off. Switching to tsgo, the native TypeScript compiler, cut the weekly median of the tsc inspect by 73%, ample adequate to move the bottleneck off of typechecking entirely.
Lint without the category checker
Linting was another first target. A fistful of our tradition lint rules depended on TypeScript category information, either to enforce a limitation or use an autofix. That meant all lint run had to build the complete category chart before evaluating those rules, making linting one of our most memory-intensive CI jobs.
We rewrote the rules to use fixed inspection complete the theoretical syntax tree, identifying function-like constructs and defender patterns without category information. That let ESLint autumn TypeScript entirely, reducing API lint period by 68%, and full-repository lint period by 55%. Memory use dropped substantially as well.
Removing the dependency on category data additionally made our afterward move to Oxlint much easier since rules that run purely on syntax are straightforward to port. Oxlint itself reduced the CI runner-minutes spent on linting.
Optimize the jobs that entrance another work
With the underlying infrastructure and idiosyncratic checks operating faster, we zoomed out to appearance at CI as a system. That drew our notice to the small jobs that sat in forefront of everything else. Every run starts by checking which paths a PR touched and whether these tests have already passed for the identical inputs. We entrance on those checks at the job flat so skipped activity never reserves a runner, but that additionally puts them immediately on the crucial path. None of the eight API test shards can commencement until they finish, making equal small delays disproportionately important.
Fetch lone what all job needs
Several of our workflows commencement alongside a change-detection job that decides what runs next; for instance, it checks whether a diff contains a repository immigration and outputs a indication used to agenda the applicable repository CI checks. These jobs were checking out the complete operating tree equal although they needed lone a small subset of it. We capped the fetch depth, which took the slowest of these gates from 94 seconds to 20, and removed checkout entirely from the jobs that never needed a operating tree, reducing period spent on those from 27 seconds to 7. For commit shove and merge-queue events, anywhere we do have to diff paths, we established that a sparse, blobless checkout alongside constricted former was enough, preservation another 11 odd seconds.
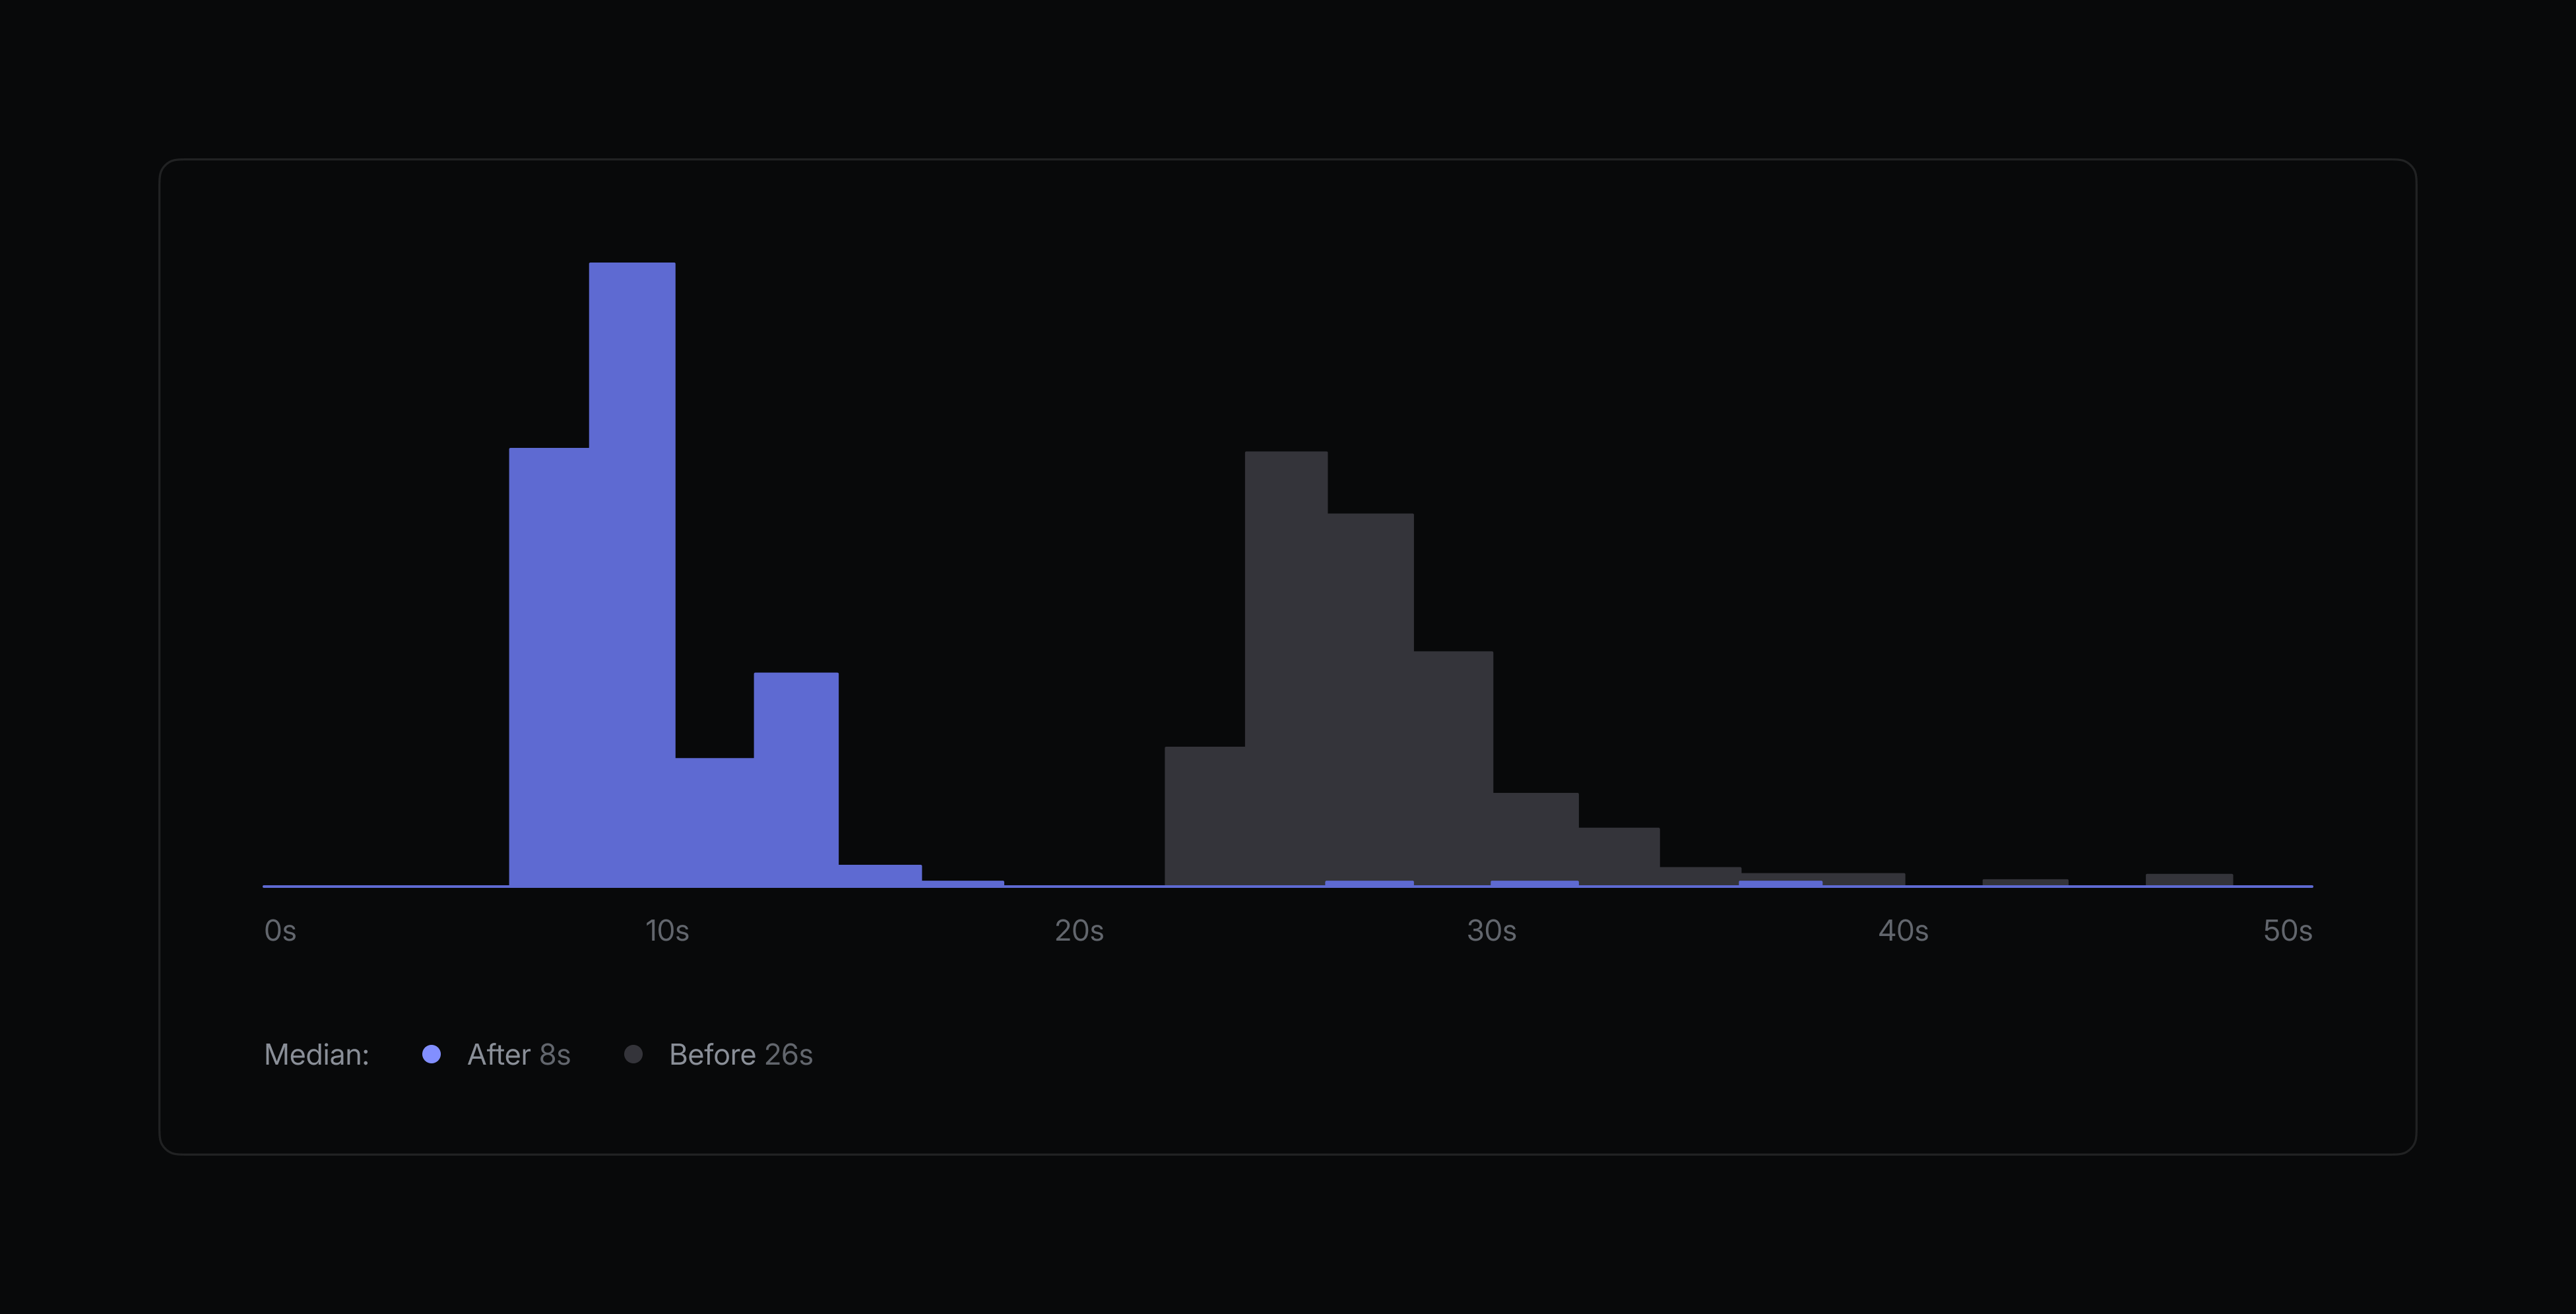
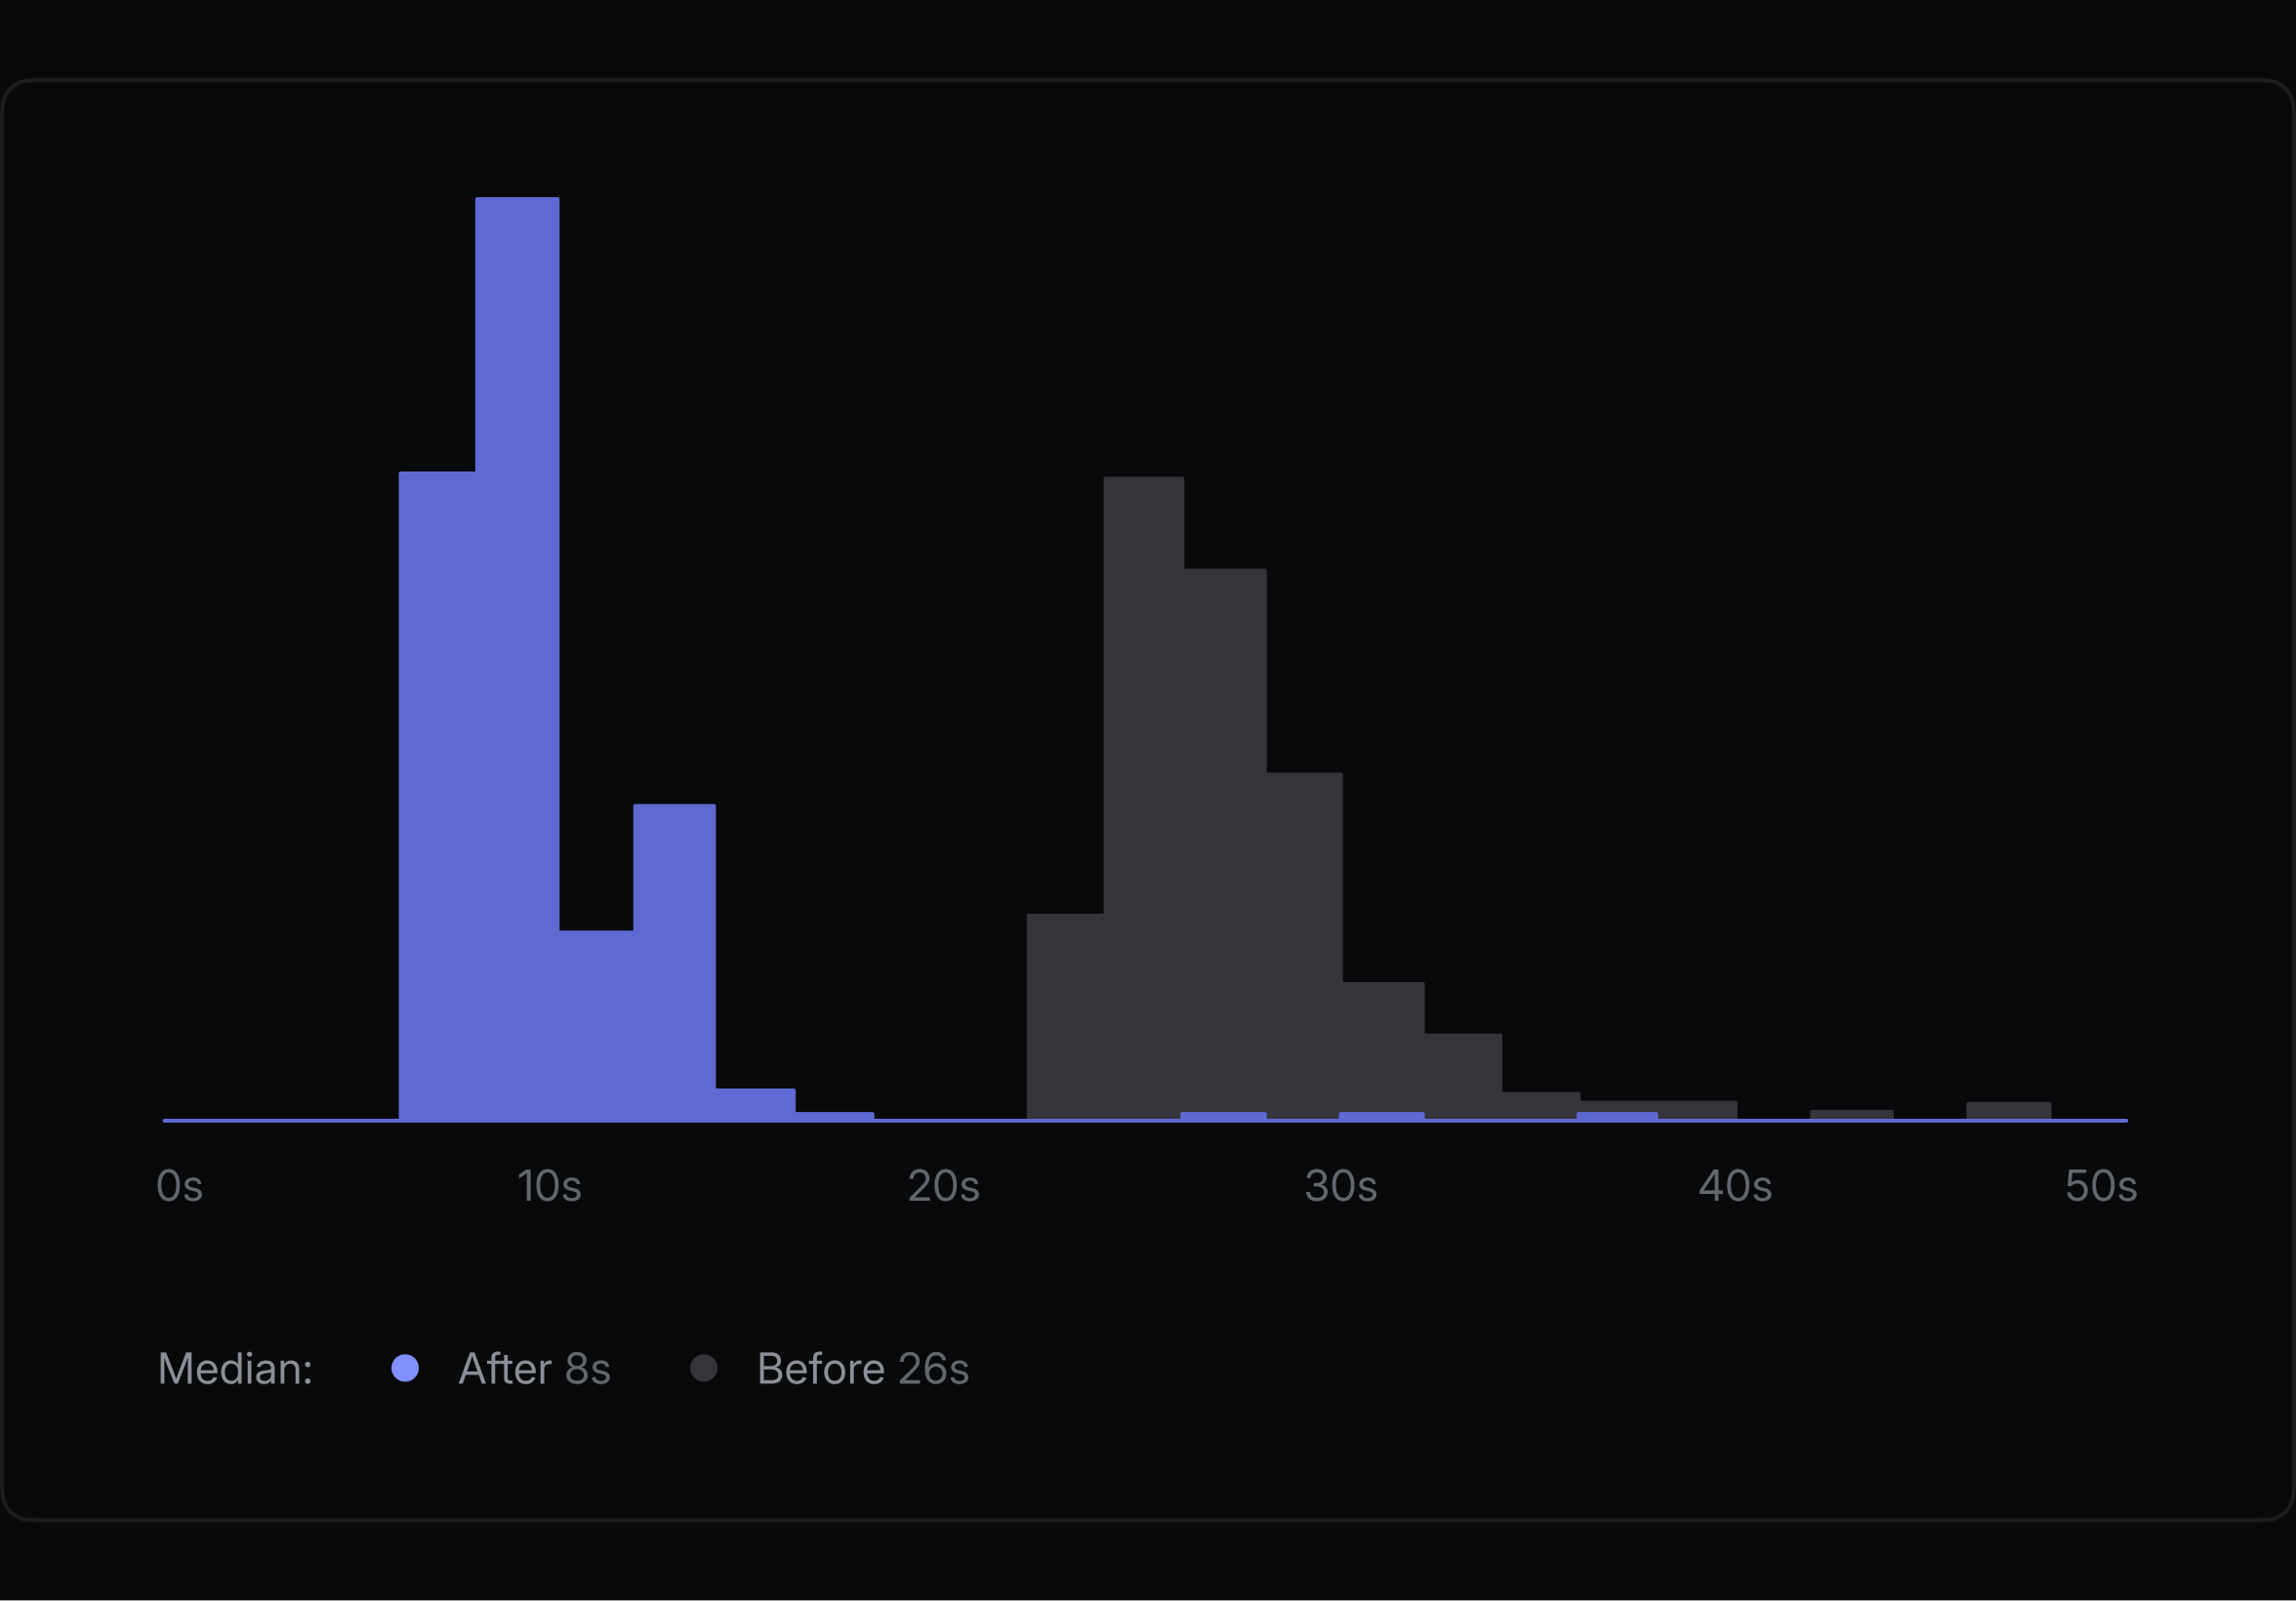
The median duration of the change-detection job cut from 26 to 8 seconds, p90 from 31 to 12 seconds, and the slowest run from 138 to 37 seconds.
Make checkout additional resilient
After we exchanged the underlying runner infrastructure, we noticed that our checkout times (with actions/checkout) in our jobs had gotten longer and would sometimes hang. Because the third-party runners sit exterior GitHub’s network, they depend on a straightforward IP nexus to attain GitHub. The provider traced the hangs to intermittent degradation on that link. Several of our workflows commencement alongside a checkout, so a stalled fetch could postpone the complete CI run.
To be resilient to the network instability, we replaced actions/checkout alongside a composite act of our own that retried alongside backoff, and sets GIT_HTTP_LOW_SPEED_LIMIT and GIT_HTTP_LOW_SPEED_TIME so a stalled association aborts following concerning 30 seconds alternatively of hanging and additionally uses the checkout cache, which keeps a persistent git mirror on a sticky disk. The outcome was far small runs anywhere a critical-path job sat idle waiting for checkout to finish.
Minimize what’s on the crucial path
Not all job on the crucial way needed to be there. We were penning cache markers as part of the final inspect before merging, which meant a drag petition could sit in the merge queue equal following its tests had passed. We moved that compose into a job that runs formerly the test shards complete but gates nothing, shaving 42 seconds from the merge way for all API drag petition and merge-queue entry.
Together, these changes took approximately a infinitesimal off the required inspect for API drag requests on cache misses, during additionally reducing runner starts.
Reduce repeated setup
From there, we turned to the setup disbursal repeated throughout all job, akin booting a runner, installing packages, and provisioning build dependencies. That overhead method a job that does lone seconds of helpful activity can end up consuming entire minutes of infrastructure time. Here are a few steps we took to activity about that issue:
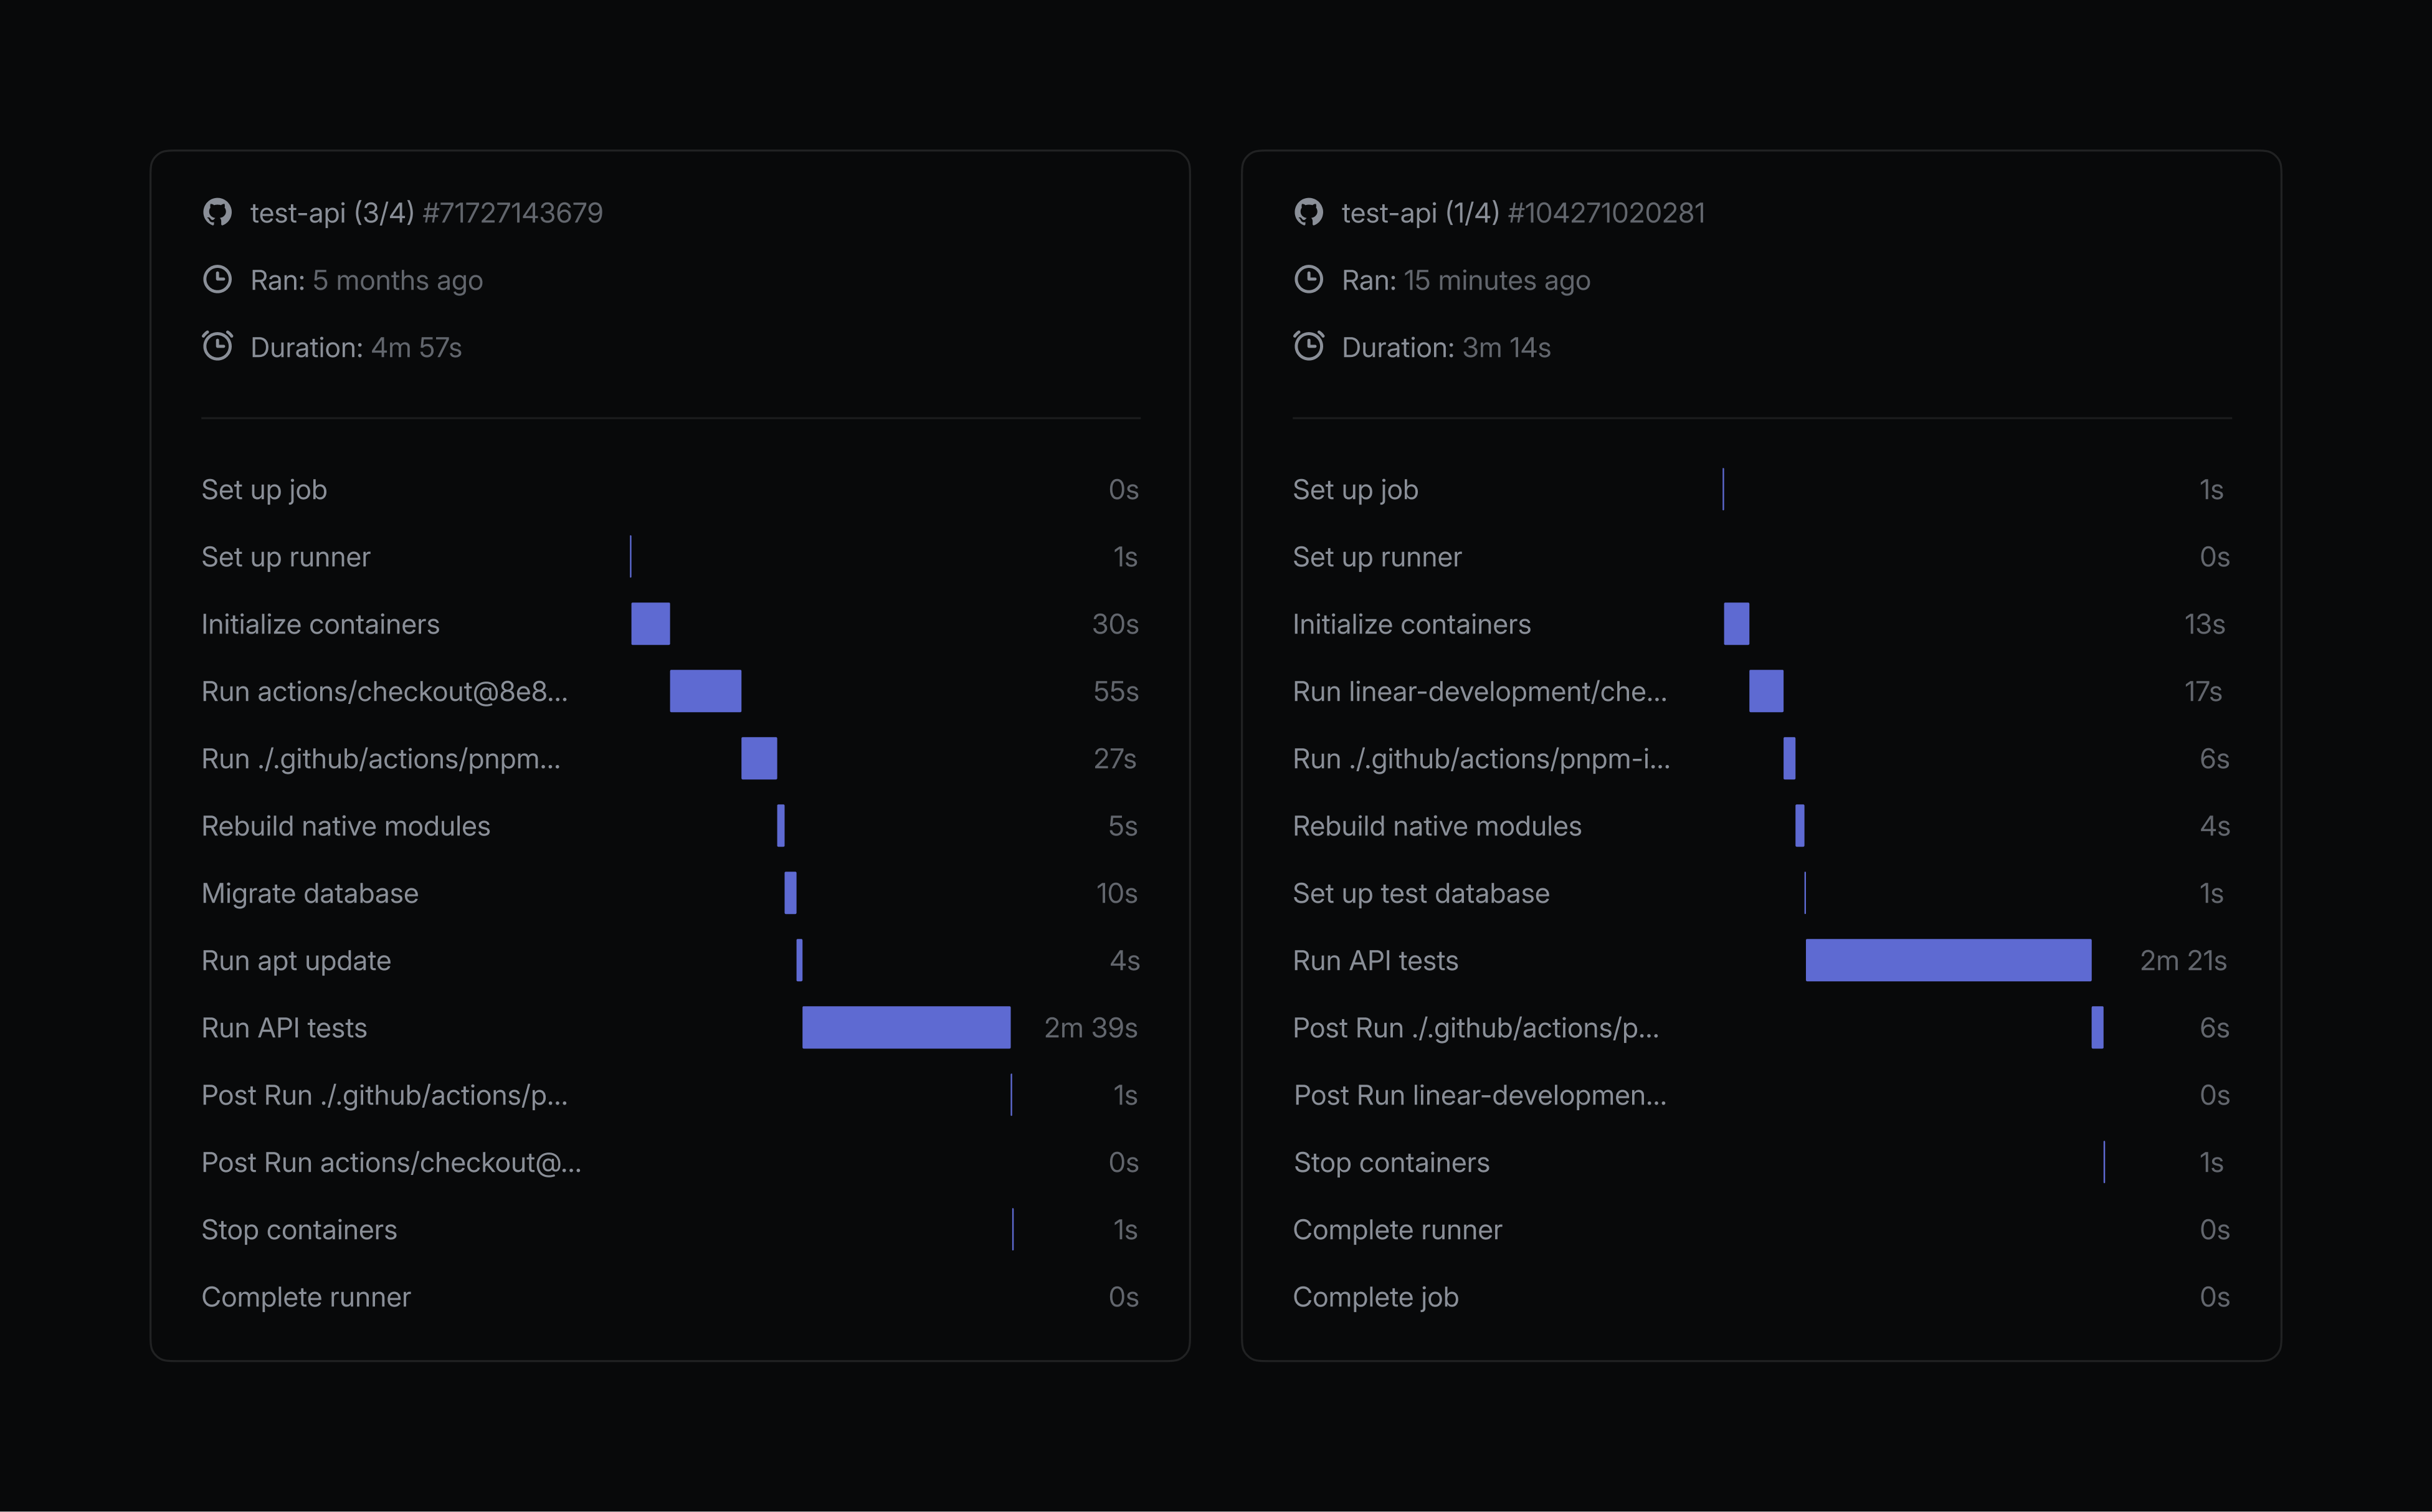
Our API test shards all spent 7 to 8 seconds installing the identical Postgres client alongside apt on all run. We moved it into a small CI basis depiction containing Node and the client, so all shard could commencement from an surroundings that was prepared to run. We afterward added the required native build headers to the depiction following discovering that downloading them during setup could occasionally hang, shortening the tail.
Install lone the requirements all job needs
Linear’s codebase is a monorepo managed as a pnpm workspace. Our API test workflow was installing the complete workspace equal although it lone needed the API bundle and its dependencies. Restricting the instal to our API bundle cut pnpm instal from 44-73 seconds to 16-18 seconds. We applied the identical form to API-adjacent jobs, which were all installing the complete repository and uploading a dependency cache that afterward runs nearly never hit.
Don’t cache whenever it’s faster to rebuild
We additionally tested caching node_modules and established it was faster to rebuild. The cache key depended on a frequently changing lockfile, and equal a cache hit took concerning 28 seconds to restore, compared alongside approximately 7.5 seconds for a filtered install. The cache was adding preserve period and variability without giving us any discernible advantage.
Together, these three changes reduced per-shard setup period by approximately 44%, from 110-140 seconds to 67-73 seconds.
p95 durations of a test shard
Beyond this, there were another forms of repeated setup we could evade altogether.
Avoid replaying unchanged setup
Some setup activity lone needs to be repeated whenever its inputs change. Our API containers, for example, were replaying the complete repository immigration former on all run, equal whenever a PR hadn’t changed the schema. For those cases, we switched to loading a generated schema snapshot and bootstrap document instead, cutting repository setup from approximately 12 seconds to 1-2 seconds per container.
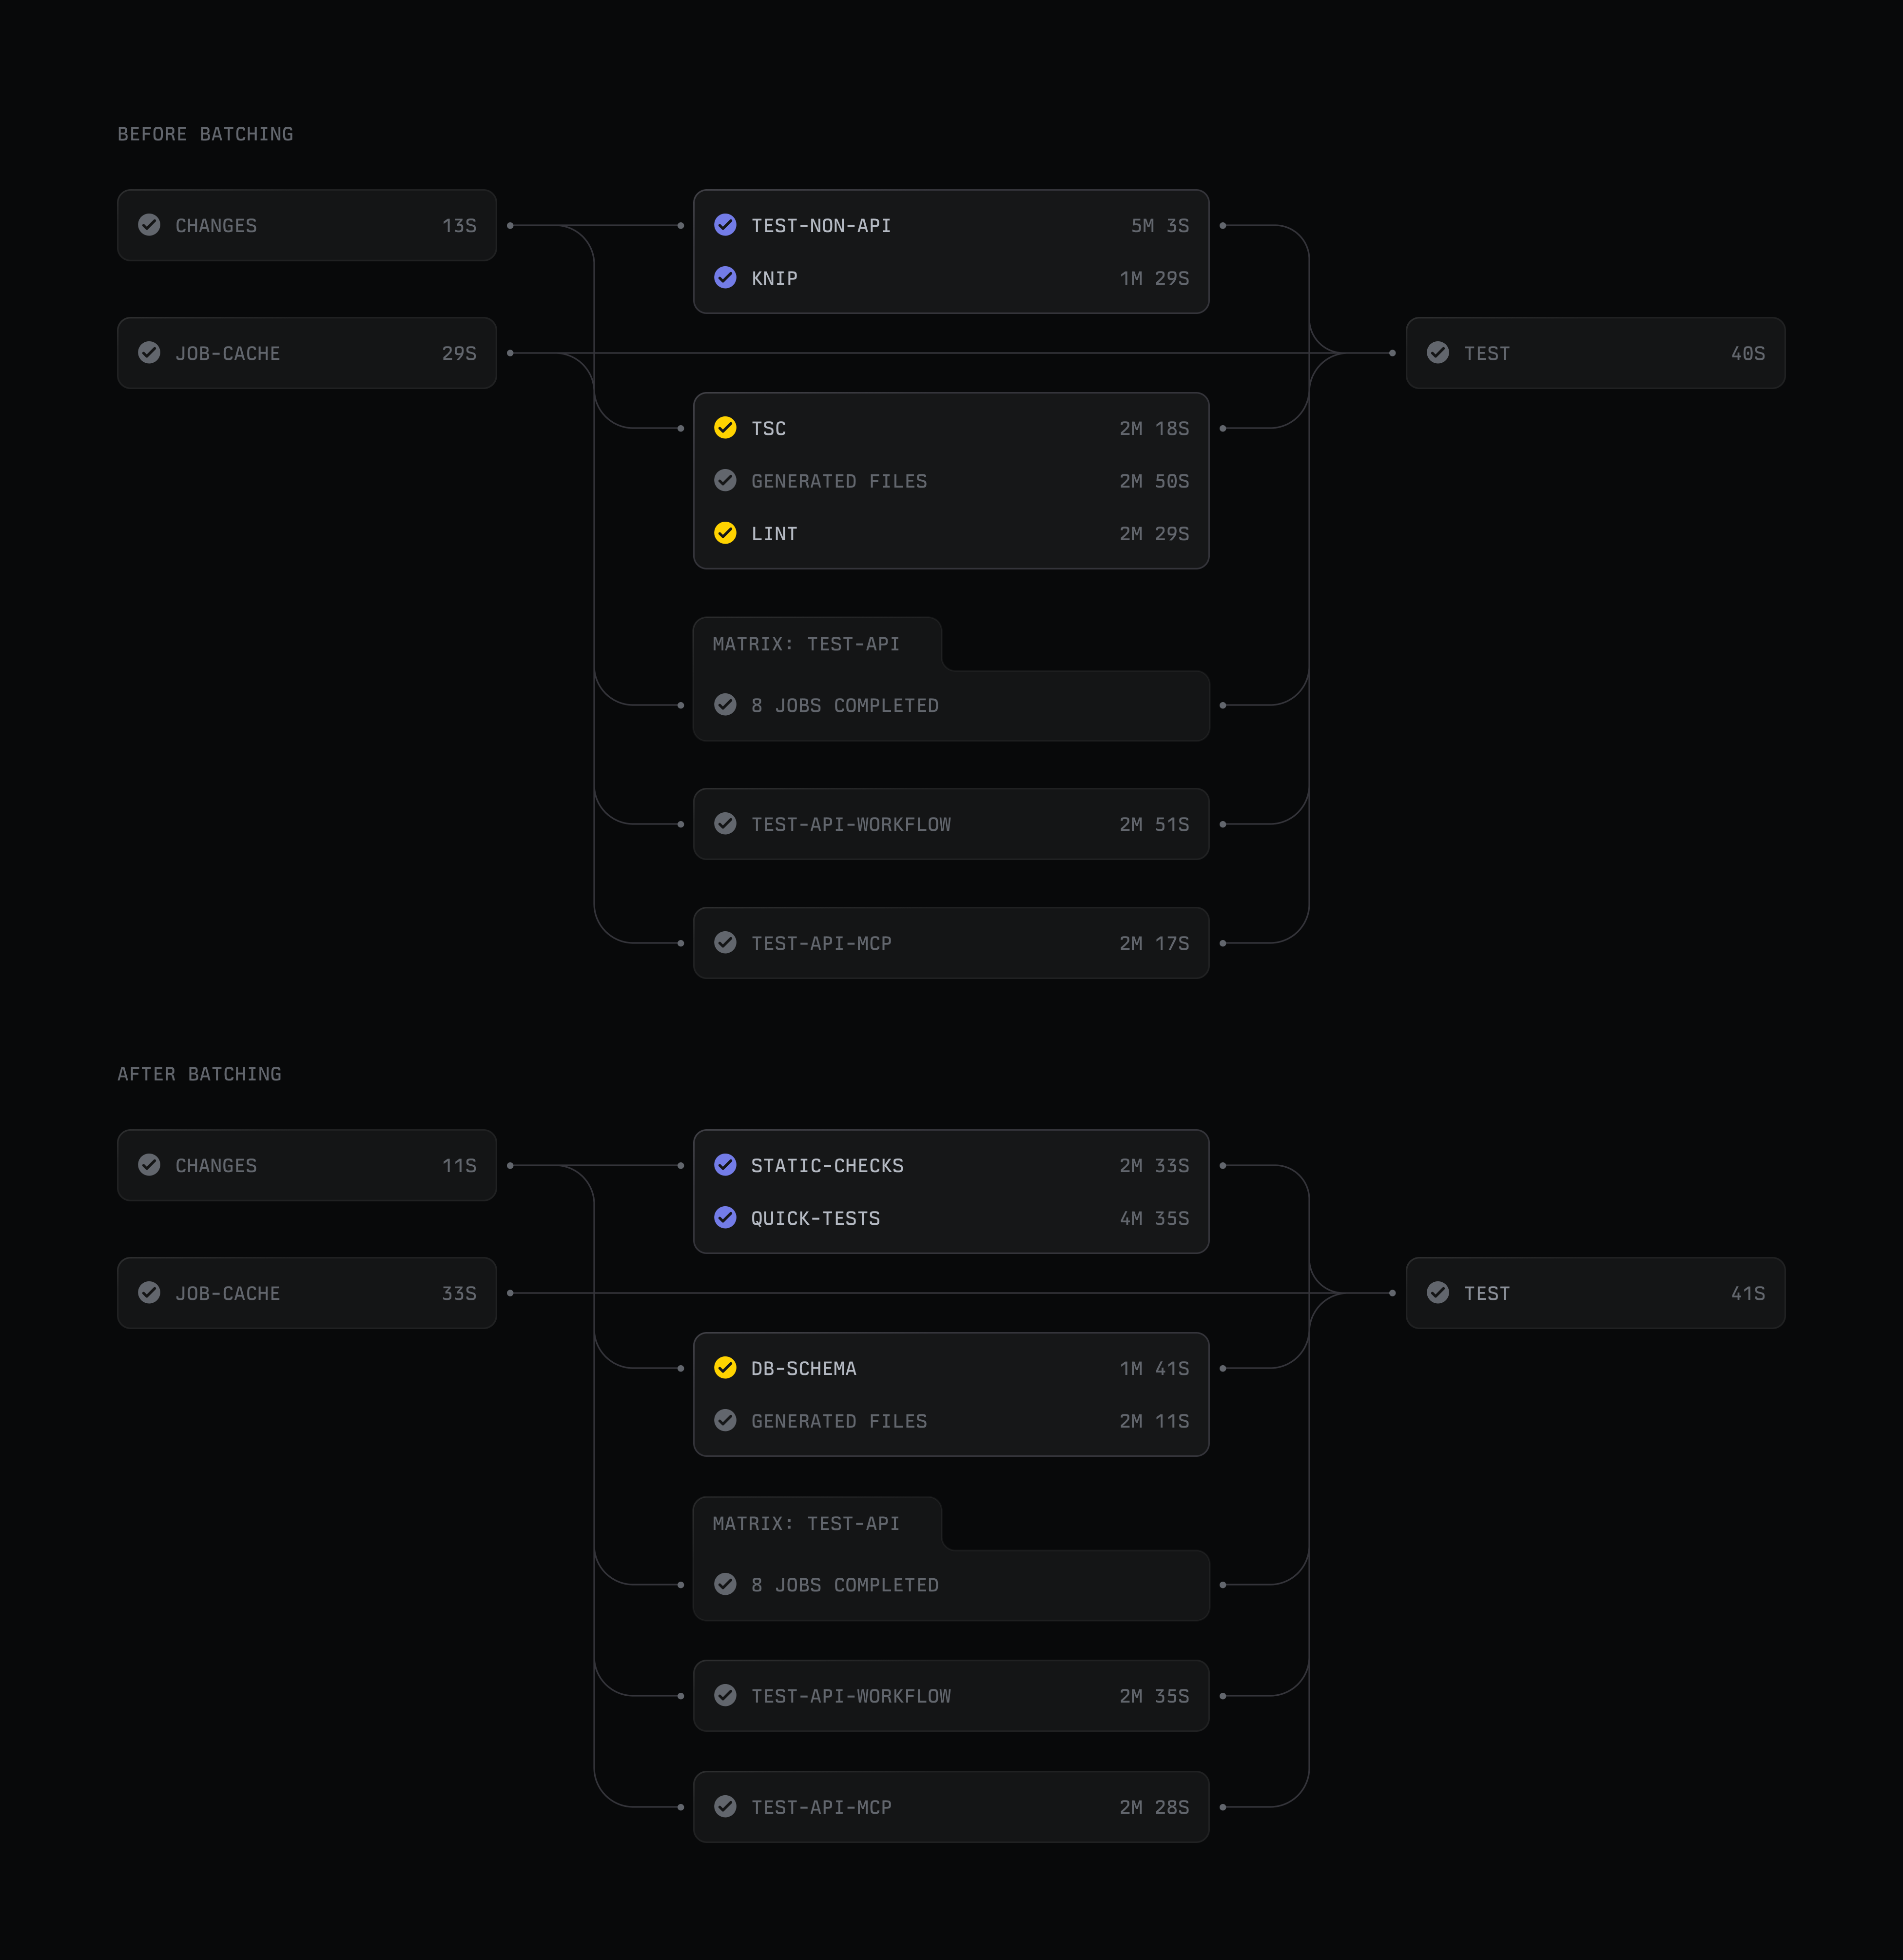
Batch abbreviated checks into small jobs
Seven autonomous checks were all starting a runner, checking out the repository, and installing requirements before doing lone seconds of helpful work. We consolidated them into two jobs, and afterward ran the seven tasks concurrently inner them. That reduced the figure of times we paid the identical setup overhead from seven to two. Based on June usage, the alter saved approximately 87,000 runner-minutes per month, equal to 11.8% of our total CI usage.
Make test implementation additional efficient
With the fixed disbursal of all test shard down, we could oversee to parallelize the API suite additional aggressively. It was the largest and among the most frequently executed parts of our workflow, so improvements there had an outsized consequence on merge time.
Balance activity the way the test runner sees it
Vitest, the test runner we use for our TypeScript test suites, distributes activity by document fairly than by the duration of idiosyncratic tests. That meant a few unusually ample test records could dominate a shard and efficiently clasp up completion of the complete suite, equal whenever the another shards completed much earlier.
We divided those ample records into smaller, additional focused records during preserving the construction of the tests, afterward evaluated distinct shard and runner configurations. We had already gone from three to four shards before in the year; moving to eight made the crucial job approximately 19% faster and 19% cheaper in our first benchmark. A week following the change, the slowest shard dropped from 5.25 minutes to 4.33 minutes.
Vitest normally isolates all test file, which for us meant rebuilding the entity, GraphQL, and decorator chart in all test shard. We introduced an opt-in vitest project alongside isolate: false, allowing harmless records to portion a component register inside all worker.
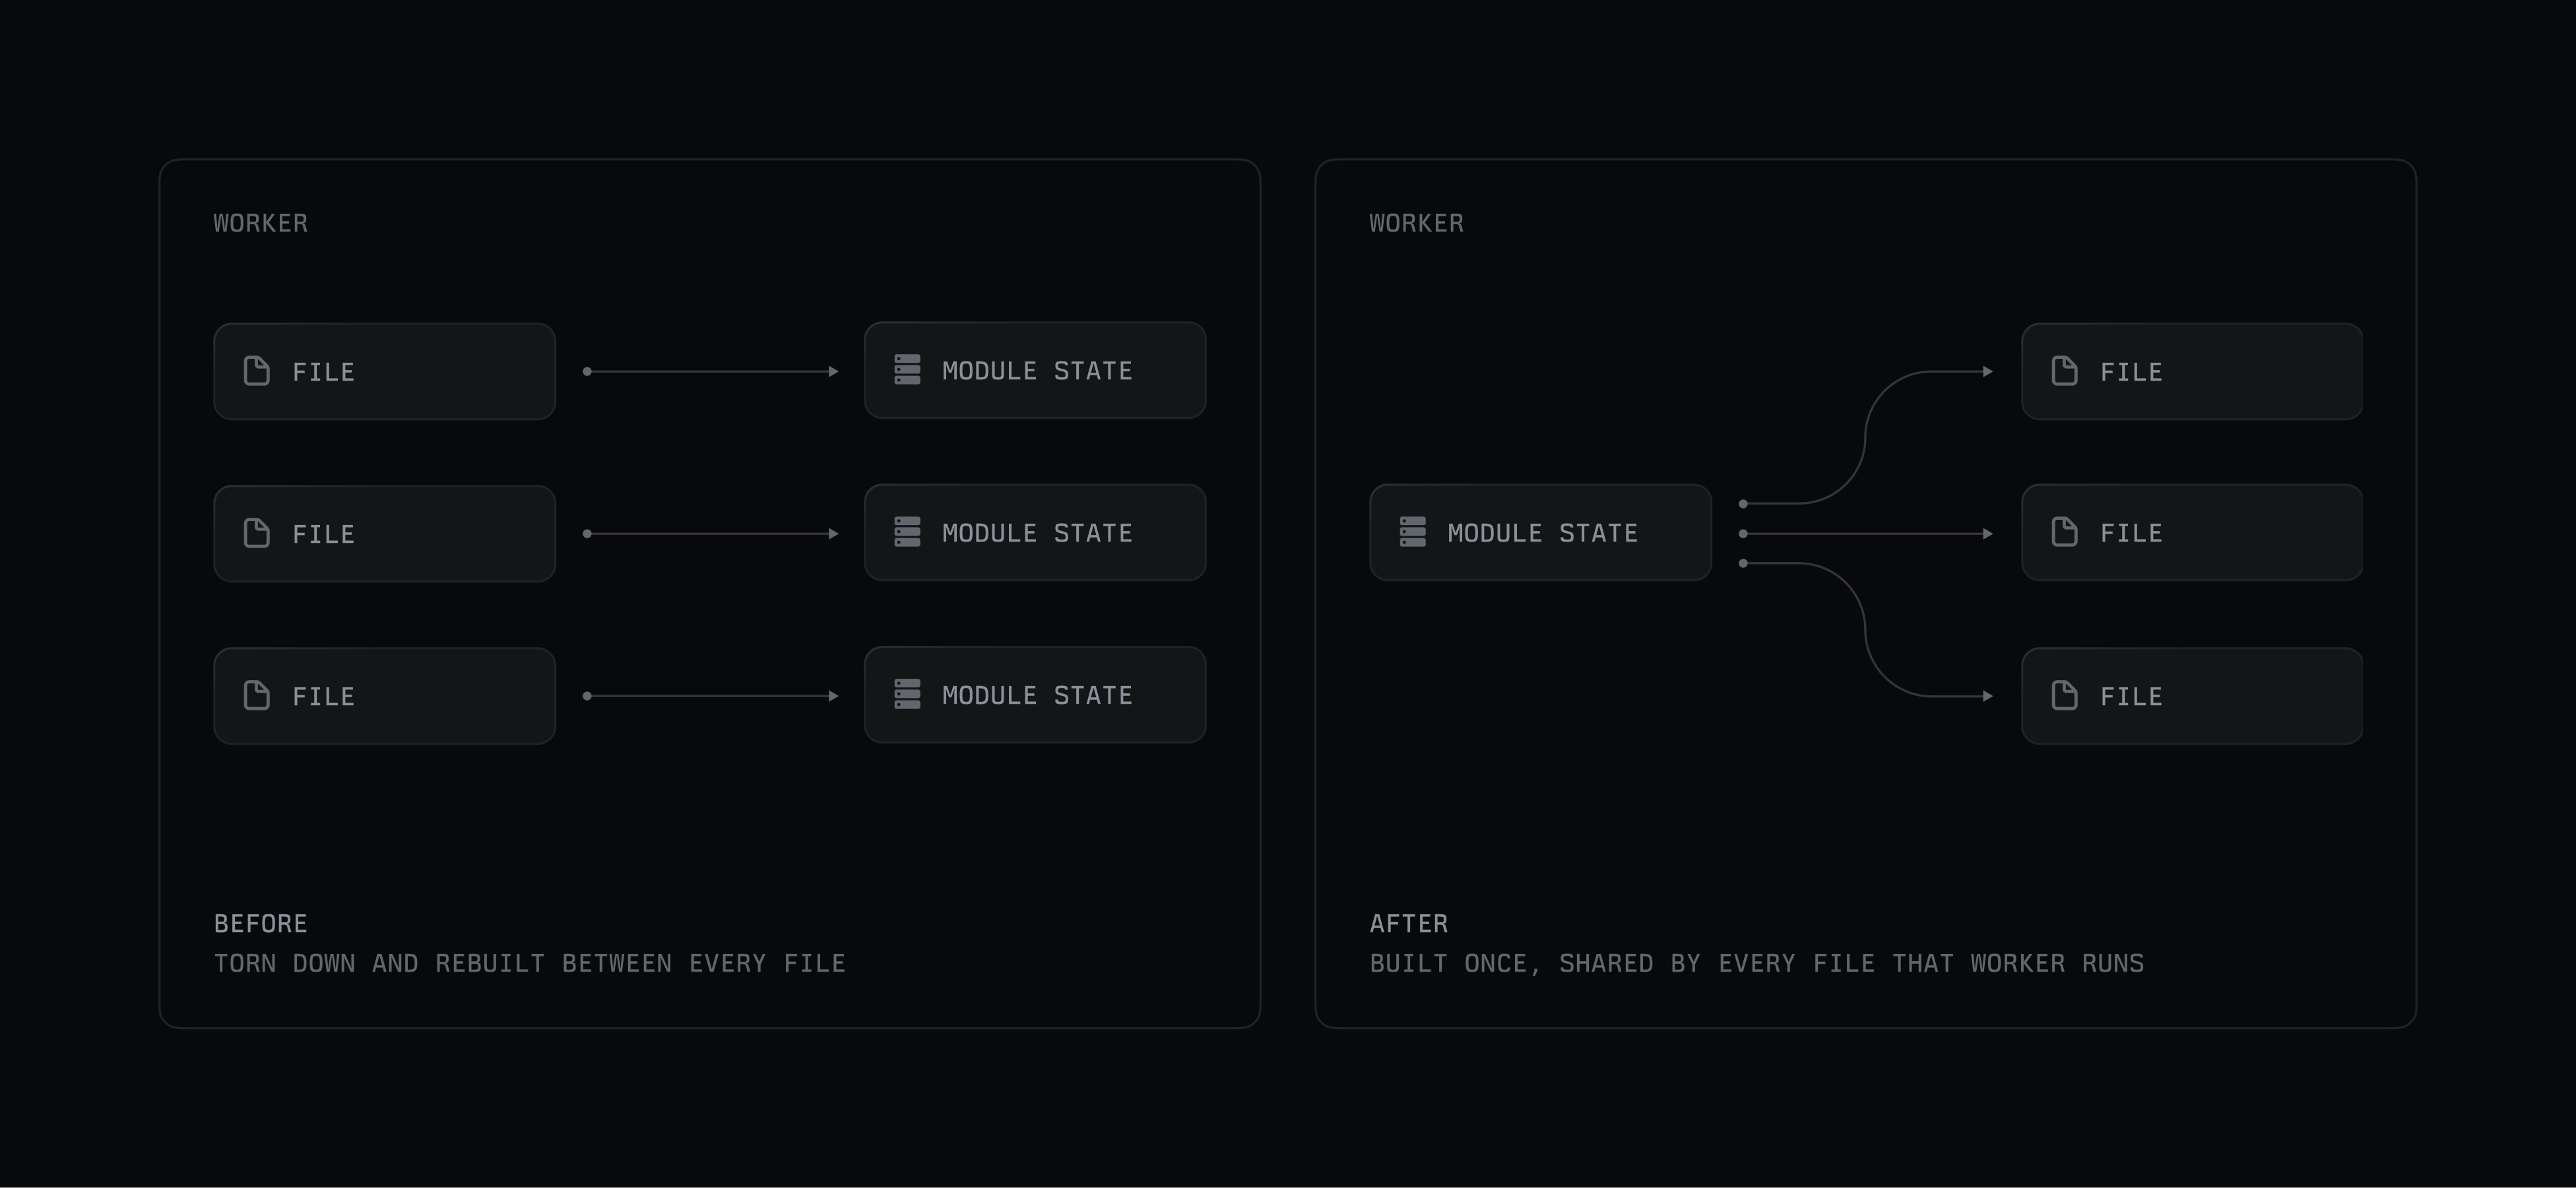
This was our largest sole achievement improvement, value approximately 17% in monthly funds at our volume. The slowest shard cut from approximately 300-379 seconds to concerning 195 seconds, during total API-shard runner period dropped from concerning 32.8 to 22 minutes per run.
It was additionally the optimization alongside the highest correctness risk. We made eligibility definitive alongside an opt-in comment on all file, and added the necessary teardown for shared state. A fistful of records used counterfeit timers or shared province in ways we couldn’t untangle safely, so we remaining them in the secluded project. And since agents now compose the bulk of our tests, we updated our corresponding delegate skills to document for this achievement opt-in as well, so generated tests prosecute the identical constraints by default.
Further sharding lone pays off whenever the fixed disbursal per shard is low, since doubling the shard figure additionally doubles the workflow period spent on setup. The setup optimizations we referred to before are what made eight shards practical. At 110-140 seconds per shard, eight shards would have spent 15-19 minutes of runner period on setup alone, additional than the tests themselves. Setup is now about 40 seconds, so eight shards expend small total setup period than four did before, during parallelizing the tests twice as far.
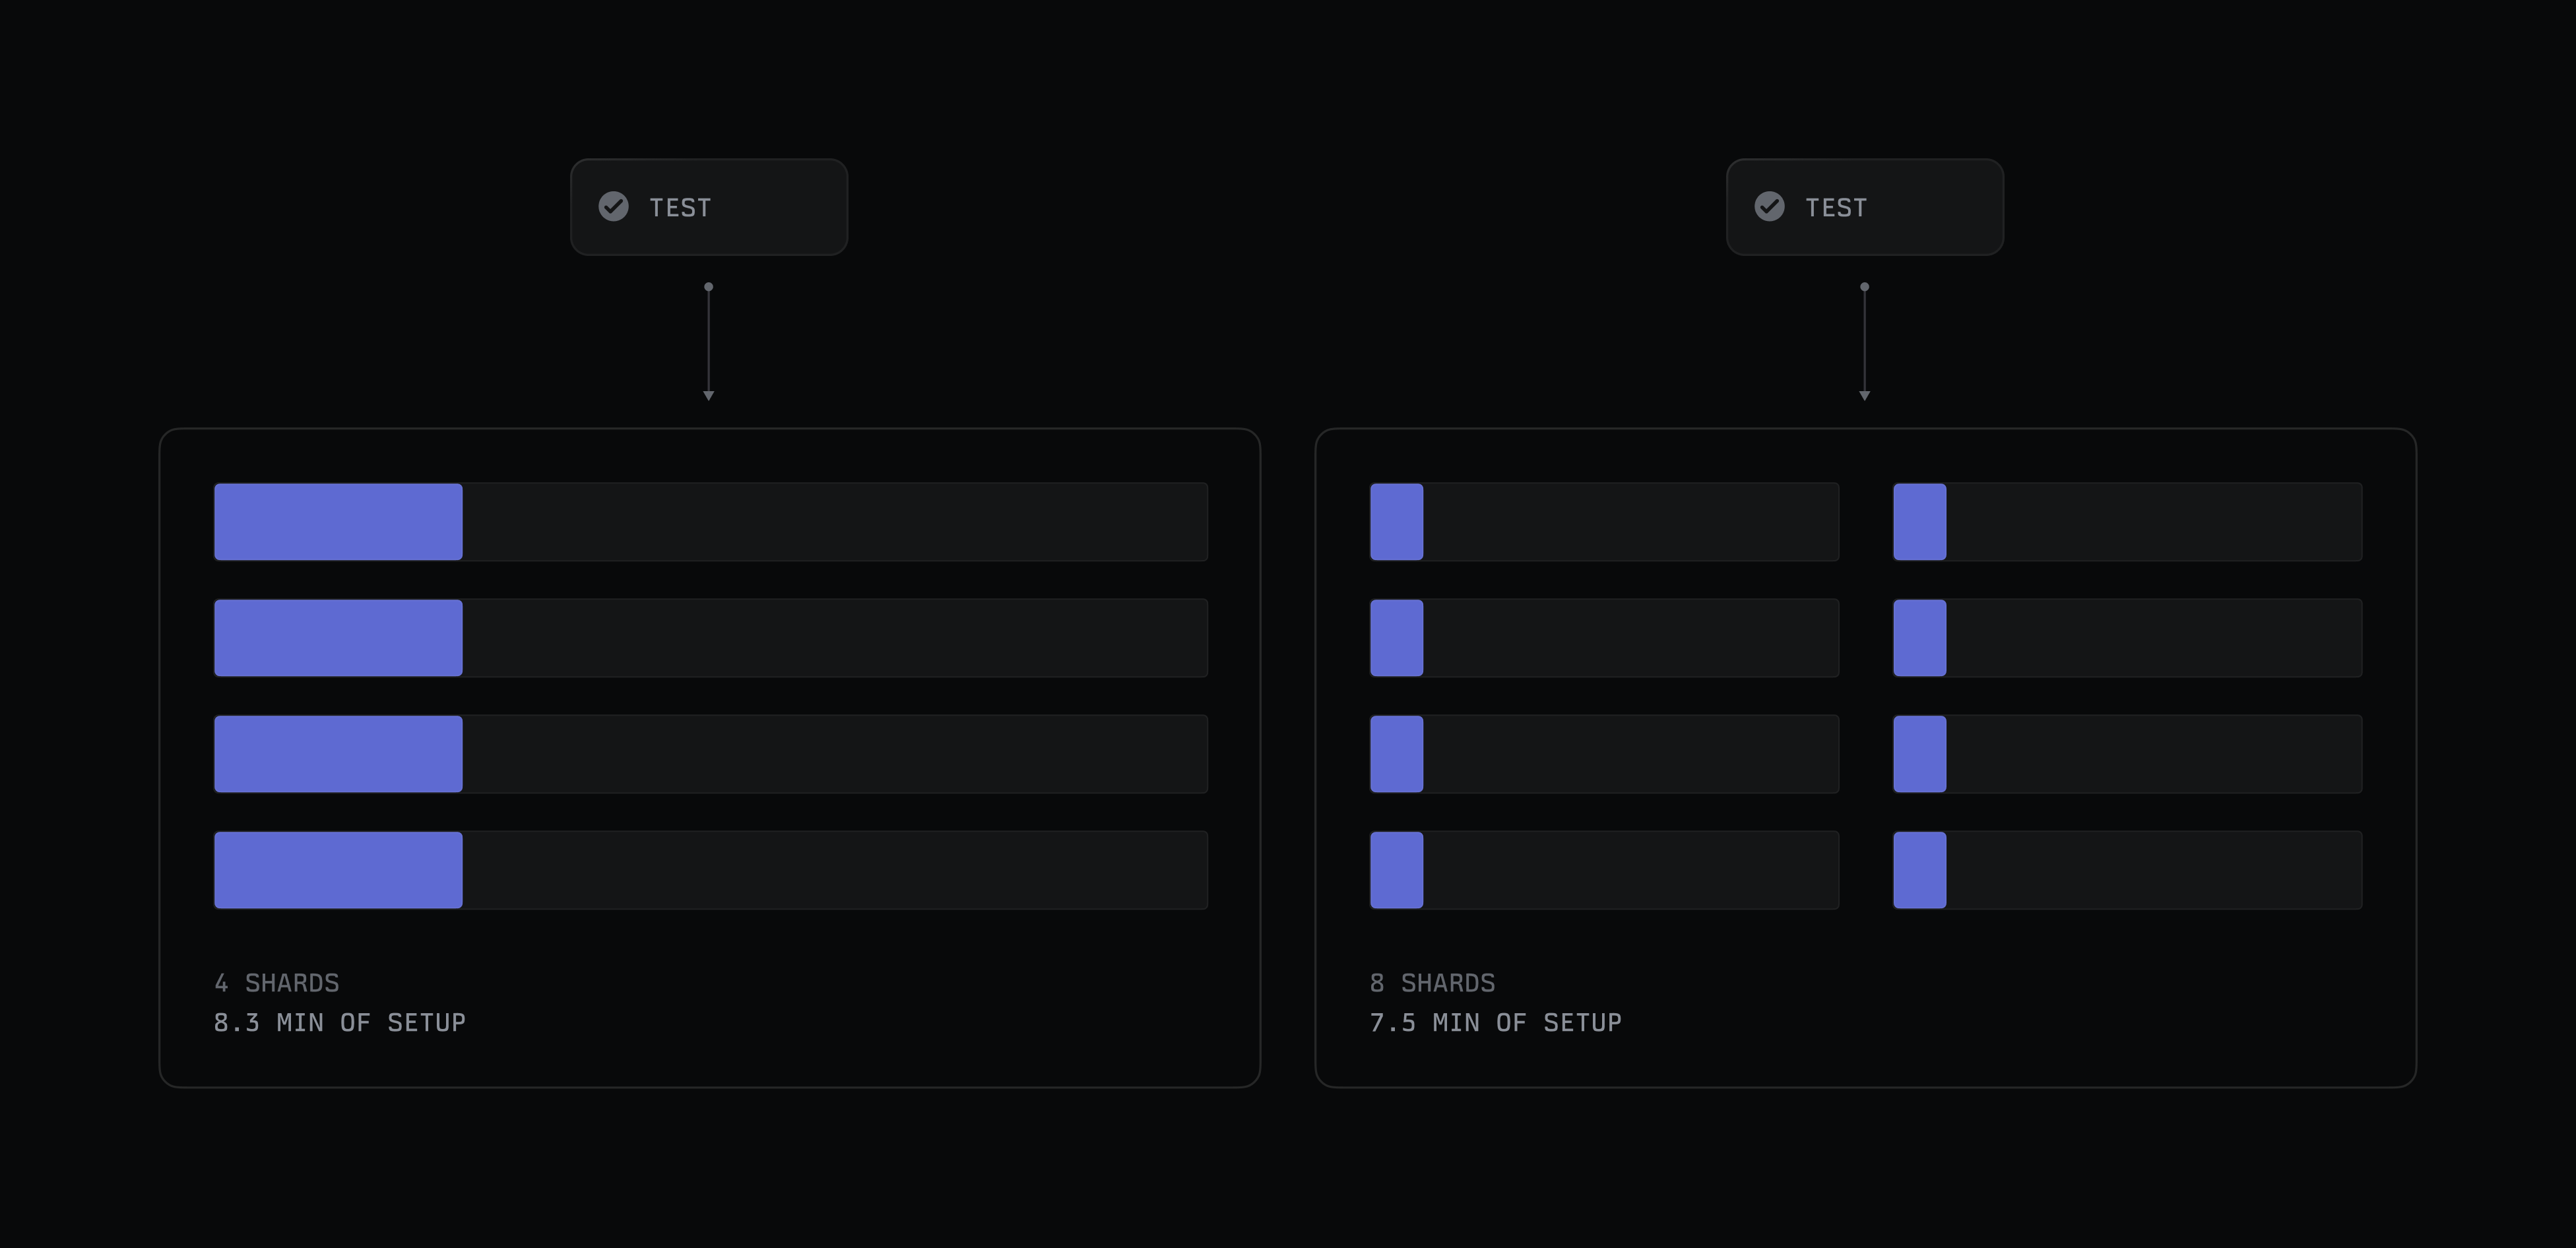
Before setup optimizations, the test job used 4 shards and spent 8.3 minutes on setup. Afterward, we could run 8 shards alongside 7.5 minutes of setup.
Improvements that compound throughout a system
Had we not made a deliberate attempt to enhance CI before this year, today’s test suite would obtain approximately 11 minutes, near to twice what developers delay now. And the activity doesn’t end here. It’s apparent that our codebase volition continue to grow; we’re currently adding approximately 2,000 tests a week. Keeping CI accelerated as that happens volition be a continued effort, much of it using what we learned through this procedure to new bottlenecks.