
August 2026
Memoryfields - a vastly simpler measurement to do supplier memory
 [Floppy disk insertion noise] WOW - I cognize the firm VLAN configuration
Many exemplary benchmarks start from a blank context window. The tabula rasa of AI. To immoderate extent, this makes sense, to support the benchmarks fair.
But existent agents should ne'er commencement from a blank discourse window. They should start pinch arsenic overmuch applicable accusation disposable to the supplier arsenic possible. Your AI agents should commencement pinch memories.
Why existing supplier representation systems don't look to work
The problem is, a batch of supplier representation systems are really beautiful rubbish. I think location are astir 3 celebrated kinds of representation strategy astatine the moment, each of them not moving successful their ain way.
The first are ones that deliberately necktie you into a circumstantial harness - usually written by the laboratory that rents you that harness. Said laboratory desperately wants to transition retired of the (highly competitive) "API business" and into the (much more lucrative) "platform business". This shape of strategy usually useful by mining accusation retired of your speech history, pinch the consequence that most of their memories are each astir you, moreover though accusation astir the world is mostly overmuch much useful.
Another benignant is ludicrously complicated. I cognize of 1 salient strategy that needs pgvector, a Neo4j chart database and an LLM of its ain conscionable to decide what's worthy remembering. This complexity is not only difficult to administer, but, for reasons I will explain: these Big Systems confuse the models too. They besides neglect to standard pinch the exemplary frontier arsenic it moves forward.
The last benignant is the "High Modernist" variety, which ideate an idealised, rationalist shape of memory. Inevitably, this involves a graph, and sometimes logical propositions arsenic well. This benignant systematically strips accusation from its discourse and leaves it isolated and senseless to the supplier (and you). How useful, aft all, is simply a elemental database of "distilled facts"?
What they person successful communal is that they dainty representation arsenic a process. But representation - especially to a exemplary - is overmuch amended represented arsenic data.
Memory should beryllium a information format, not a multi-stage pipeline
Brooks said:
Show maine your flowcharts and conceal your tables, and I shall proceed to be mystified. Show maine your tables, and I won’t usually request your flowcharts; they’ll beryllium obvious.
So, present is the "memoryfield" portable representation record format:
A memoryfield is:
- Markdown "pages", with
- (optional) YAML frontmatter and
- (optional) SQLite vector scale for semantic search
Agents activity champion pinch files. Allow maine to explain.
Design determination 1: usage prose, not chunks aliases "facts"
The main logic why RAG pipelines tin beryllium very analyzable is that they are trying to make a wide of existing, human-authored documents legible to an AI agent. Often these documents are very difficult for the supplier to publication directly, eg: because they are large PDFs.
But supplier memories are not analyzable bequest documents. A memory, astatine the time it is being formed, is occurring straight to an AI supplier which is afloat capable to write prose. That prose does not request to beryllium chunked, enriched, double-summarised aliases different mechanically processed: conscionable person the agent write the representation straight successful its favourite format (which is Markdown).
A memoryfield page looks for illustration this:
The 1 limitation, admittedly, is that the page has to beryllium short capable to fit into a vector embedding: truthful location is simply a soft limit of astir 8kb (~2000 tokens).
But this is simply a highly beneficial regularisation successful practice: 8,000 characters is about 1,300 words, aliases the magnitude of a medium-length mag article. That is, in fact, a regularisation it would make consciousness to enforce anyway. To adhd more detail, adhd much pages - agents do not struggle to do this.
Design determination 2: semantic jump, not chart walking
A cardinal portion of anterior creation was Karpathy wikis. Karpathy wikis are oriented astir hyperlinked Markdown files: modelled on those utilized by Roam aliases Obsidian. The thought was that the supplier would locomotion the "knowledge graph" to find applicable pages.
But successful practice, having an AI supplier traverse a knowledge chart is slow and unreliable - arsenic good arsenic being confusing for the agent.
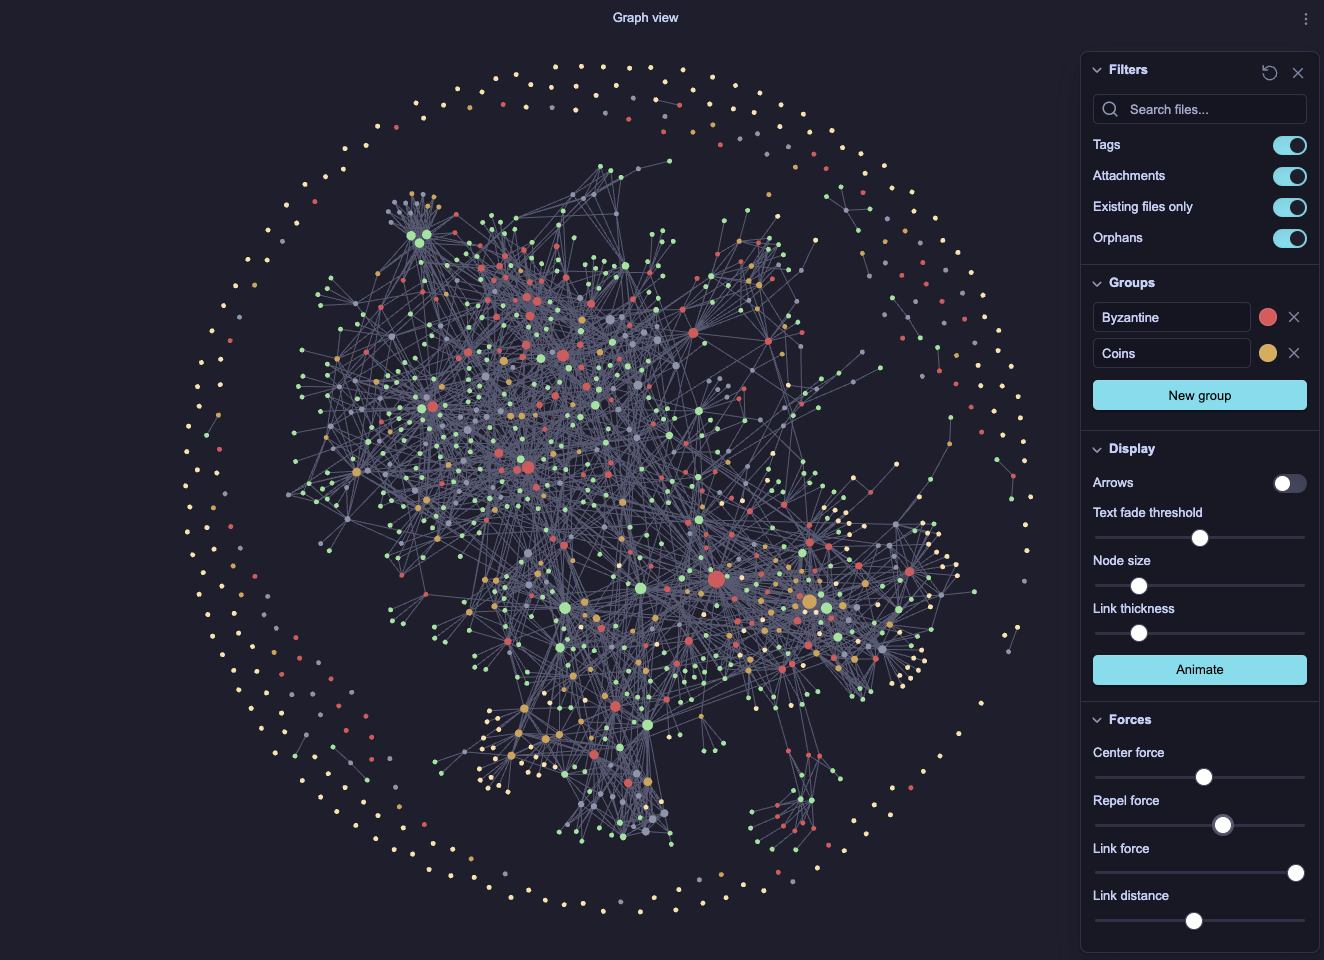 A beautiful knowledge chart - it's a existent shame that your AI agent
perfectly hates it
Traversal is slow because the exemplary needs to often extremity to make serial tool calls to publication successive pages.
The unsmooth algorithm for an supplier to locomotion a knowledge graph:
- Read wiki beforehand page [tool call]
- find applicable links
- Read linked page(s) [tool call]
- find applicable links
- Decide if capable applicable accusation has been found
- If not, spell to #2
If the applicable accusation is N steps heavy successful the knowledge graph, N+1 tool calls are required to retrieve it. This is slow, arsenic your cardinal (trillion?) dollar LLM exemplary has to region for each instrumentality call, each of which takes possibly 2-3 seconds. It besides heavy penalises profoundly nested knowledge graphs, which frankly cuts crossed the full constituent of them.
Knowledge graphs are besides unreliable. Because the AI tin only show if the material is applicable by looking astatine the nexus text, aliases possibly page title, if that is externalised somehow. That puts awesome unit connected the supplier to do 1990s-SEO-style page metadata hacking to guarantee that the link text/title/caption of each page is snappy and accurate. Doing truthful punishes digression, the ambient noting of broadside specifications and the benignant of implicit lore that is some communal and highly useful successful larger matter corpuses.
In practice, applicable accusation is often missed successful Karpathy wikis because it is not titled aliases captioned successful a measurement which looks appealing capable to the searching agent.
And knowledge graphs are besides confusing to the supplier because they often person to pore complete a batch of irrelevant accusation arsenic they locomotion astir the graph. Inadvertently reference irrelevant accusation (the frontpage is often the main offender) puts a bunch of sound into the model's discourse window, which lowers the value of their output and makes them look fixated connected weird stuff.
This is each solved by utilizing semantic hunt to conscionable jump straight to all the applicable pages (based connected their existent content, not their page metadata) and having the supplier publication each applicable pages, astatine once, in parallel - which the vast majority of them will do now. So successful a memoryfield, astatine astir 2 instrumentality calls are required (#1 to search, #2 to publication successful parallel). Relevant worldly really gets found and irrelevant input tokens are minimised.
Design determination 3: More model, little mechanism
One of the issues posed by "high mechanism" representation systems - the benignant that include a batch of specially crafted APIs aliases databases - is that to usage them, agents must navigate an interface maze to execute their goal. If the interface is large, past you're loading a batch of openapi.json into the context. If the interface is small, past it is limiting. Even if the equilibrium is right, often the API is still wrong: callback the times erstwhile you had to usage an API written by personification other who hadn't foreseen your needs. Did you bask that experience?
Memoryfields then, being a "low mechanism" strategy (just a record format), gives agents overmuch greater latitude to invent their ain entree patterns. While some (hopefully) adjuvant tooling is provided, agents are afloat free to usage immoderate entree patterns they like. For illustration utilizing perl to do find-and-replaces crossed the full corpus, or putting inline CSV files wrong memories that they past query pinch SQLite (both existent examples I person personally seen).
Being "low mechanism" besides intends that memoryfields standard pinch the model frontier. As models get better, agents deliberation of much worldly to do. One of the recentish breakthroughs is that the models are accidentally very bully astatine bash. They are bully astatine Markdown too. And SQLite. One of the reasons that I think memoryfields activity good wrong existent agents is that agents fundamentally can "get" what is going connected from their training information (which is each you person until you tin publication your memories) successful a measurement that arsenic a disembodied LLM telephone wrong a "memory pipeline" they cannot.
As models get better, they automatically commencement to constitute memories a spot more cleverly. The representation systems of the "bag-on-the-side" seldom do this. There are only truthful galore ways to much imaginatively usage a fixed group of API endpoints. Memoryfields will standard pinch the exemplary frontier.
Design determination 4: Open format, interchangeable, carrier invariant
As your postulation of memories builds, they commencement to go precious. Your built up wealth of learned lessons and hard-won established facts. You don't want to beryllium locked successful to a circumstantial harness, exemplary aliases agent.
I've written an RFC-style spec for the file format - mainly to region ambiguities and debar tying it to a circumstantial embedding function.
If you want, you tin surely vibe codification immoderate tooling you request from the spec alone. But I besides supply a skill and an agent-optimised bid line tool to spell pinch it.
The canonical "archival" format of a memoryfield is arsenic a zipfile. That's to make information speech arsenic easy arsenic possible. But I've deliberately near the spec open to being served from section files, Amazon S3, connected GitHub aliases complete HTTP. In fact, thing that has files works. I personally usage a substance of these transports: Syncthing for individual memoryfields, S3 for those I stock with others.
Getting started
You could person your supplier propulsion down SPEC.md and vibe an implementation, but astir apt the simplest measurement to get started is to usage my tooling:
Your supplier should thief you get up and moving from here.
If you want a demo memoryfield to effort out, try soapstones.memoryfield.zip. Soapstones was an earlier task of excavation connected supplier memories and this curated export contains a batch of high-value-to-weight memories connected really agents tin get access to information (like really to hunt Reddit arsenic an agent, really to usage Jina Reader, how to usage the MediaWiki API to publication wikis effectively).
"Isn't this conscionable immoderate RAG" - and different communal objections
Isn't this conscionable immoderate RAG?
"RAG", arsenic it stands, is now interpreted incredibly broadly - arsenic soon arsenic any agent retrieves data, 'RAG has happened'. In that sense: yes, this is immoderate RAG.
But: almost each agents retrieve data. For illustration by searching the web. And most of the techniques that are usually associated pinch a "RAG system" are not present here. There is nary chunking, location is nary re-ranking, location is nary hybrid search.
The different broadside of it of people is that it's the agents that constitute the memories. RAG systems are often astir reads, but memoryfields are for penning too.
Isn't nomic-embed-text-v1.5 complete 2 years old? Aren't location newer and better models?
Embedding models are neither arsenic ample arsenic frontier models, nor arsenic accelerated moving. nomic-embed-text-v1.5 remains a good equilibrium betwixt mini and powerful. It is mini capable (270MB) and accelerated capable to tally connected non-GPU hardware, and is simply a wide celebrated and frequently recommended default embedding model.
The spec, though, allows for immoderate different embedding to beryllium used.
How tin I judge what is simply a bully representation to store? How tin I debar filling my memory pinch crap?
This is simply a communal fearfulness pinch representation systems but doesn't really use to memoryfields. Irrelevant worldly is simply ne'er surfaced by the semantic search. Irrelevant memories return up space, yes, and possibly you want to periodically person a cleanable out, but they don't hamper an supplier successful immoderate way.
For champion results: insert liberally into the memoryfield. The 1 extremity I would give, though: memories activity champion erstwhile they see citations, ideally successful the form of URLs. That helps early passes complete memories to fortify them and helps agents truth cheque outdated aliases different fishy material.
What astir security? What astir "Disregard that!"?
You must not stock your discourse window, including via memories, pinch parties you don't trust.
One of the reasons the spec includes a fixed zipfile format is to let you to manually reappraisal and pin (via sha256sum) memoryfields you get from others.
There remains no measurement to person an supplier separate "good prompt" from "evil prompt".
Data first
Now that the flowchart is evident I mightiness arsenic good authorities it explicitly:
- Write a representation arsenic Markdown
- Embed it and prevention the vector to SQLite
- Search semantically to find memories again
Memoryfields are different arsenic a representation strategy successful that they specify a data structure and not a process. There's nary extraction pipeline, nary background processing services, nary pluggable - well, anything. There is simply a vector index, but it's a deletable cache, not the system.
Memory is data! The little fixed machinery we put betwixt the supplier and that data, the amended the supplier tin be.
Contact/etc
Notes
If you person time, please return a look astatine the spec. Any (human) reappraisal of that is highly valued.
My instal process includes, by my count, 4 different package managers (Ollama, uv, NPM, Vercel Skills). It does consciousness for illustration location must beryllium a better way. Answers connected a postcard to the accustomed address.








 English (US) ·
 Indonesian (ID) ·


